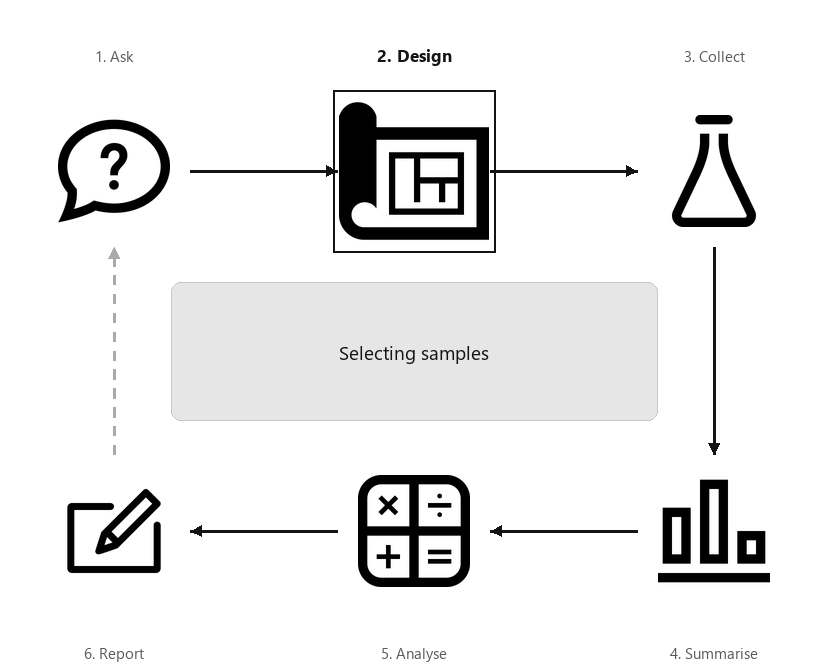
A diagram showing the six steps of research, arranged in a cycle: Ask, Design, Collect, Classify and summarise, Analyse, Report. Step 2 (Design) is highlighted, captioned “Selecting samples”.
In a research study, the researchers learn about the population by studying just one of the countless possible samples. Ideally the sample that is studied is representative of the population, so the results from the sample generalise to the population. This is called external validity. External validity does not mean that the results apply more widely than the intended population.
Suppose the population in a study is Californian home-owners. The sample comprises the Californian home-owners studied by the researchers. If the study is externally valid, the sample is representative of all Californian home-owners.
The results will not necessarily apply to home-owners outside of California, or all Californian residents. However, this is irrelevant for external validity. External validity concerns how the sample represents the intended population in the RQ, which is Californian home-owners.
Studying every member of a population is very rare due to cost, time, ethics, logistics and/or practicality. Instead, a subset of the population (a sample) is studied, and many different samples are possible.
A study of the effectiveness of aspirin in treating headaches cannot possibly study every single human who may one day take aspirin. Not only would this be prohibitively expensive, time consuming, and impractical, but the study would not even study those not yet born who might use aspirin.
The first issue is studied in this chapter. The second issue is studied later (Chapter 32), after learning about the implications of studying samples rather than populations.
Many samples are possible, and every sample is likely to be different. Hence, the results of studying a sample are likely to vary, depending on which individuals are in the studied sample. The differences between the samples, and differences in the results from each sample, are called sampling variation. That is, each sample has different individuals, produces different data, and may even suggest different answers to the RQ.
In a “population” of just \(100\text{,}\) the number of possible samples of size \(25\) is more than twice the number of people currently living on earth.
This is the challenge of research: making decisions about populations, using just one of the many possible samples. A lot can be learnt about the population if selecting a sample is approached correctly.
Almost always, researchers study samples, not populations. Many samples are possible, and every sample is likely to be different, and the results from every sample are likely to be different. This is called sampling variation.
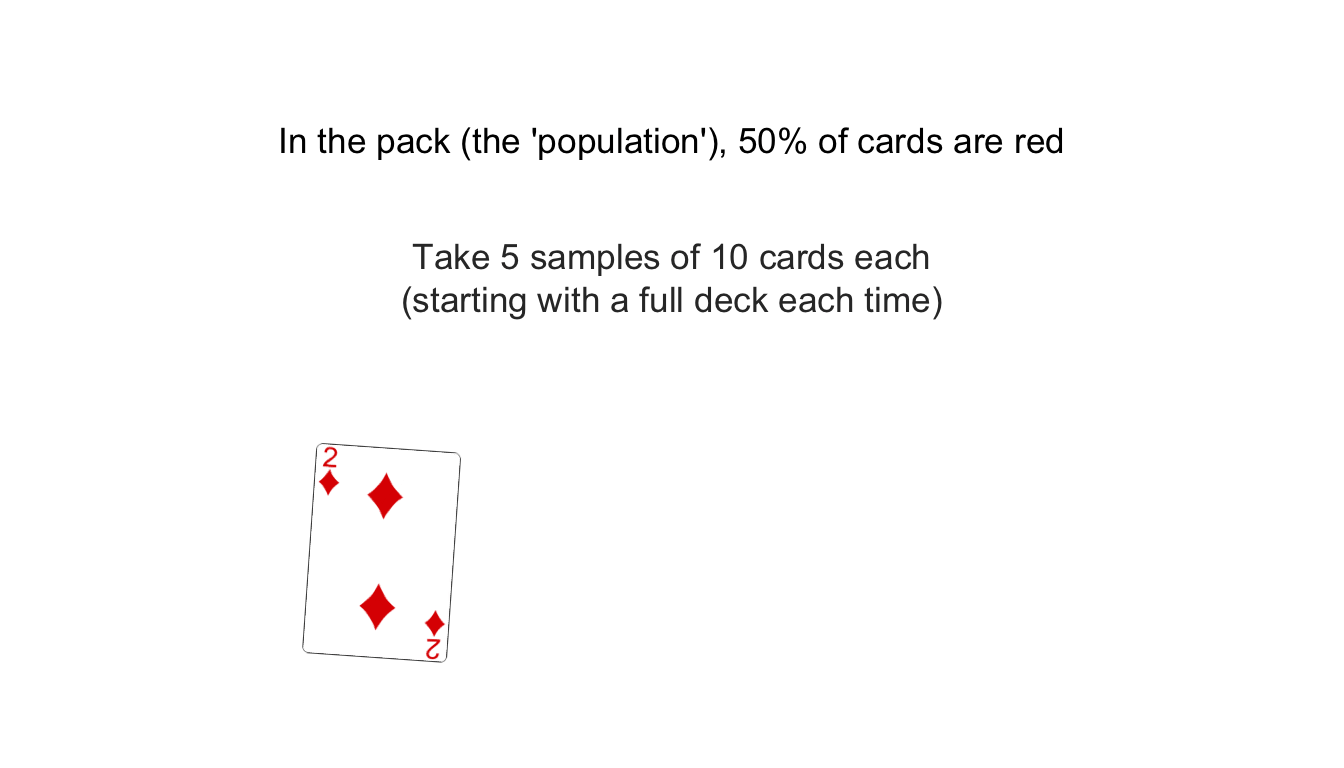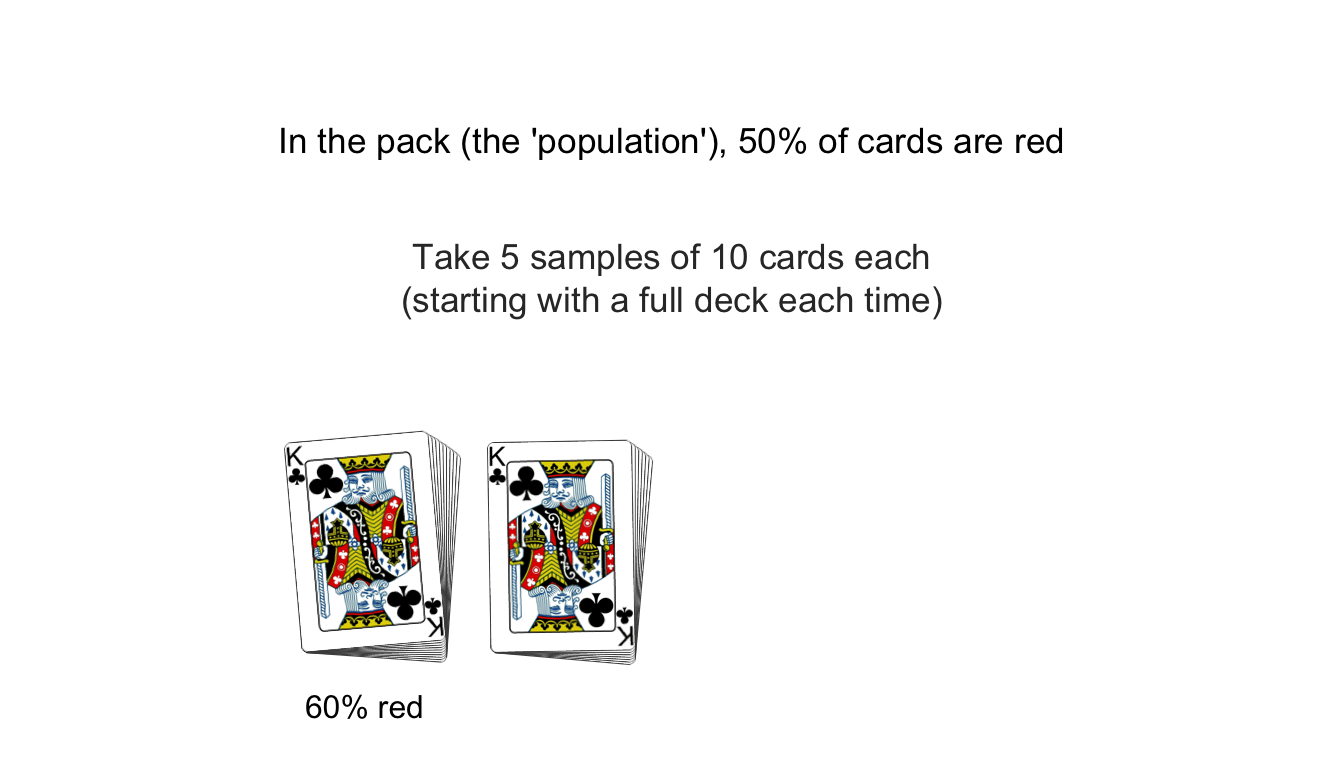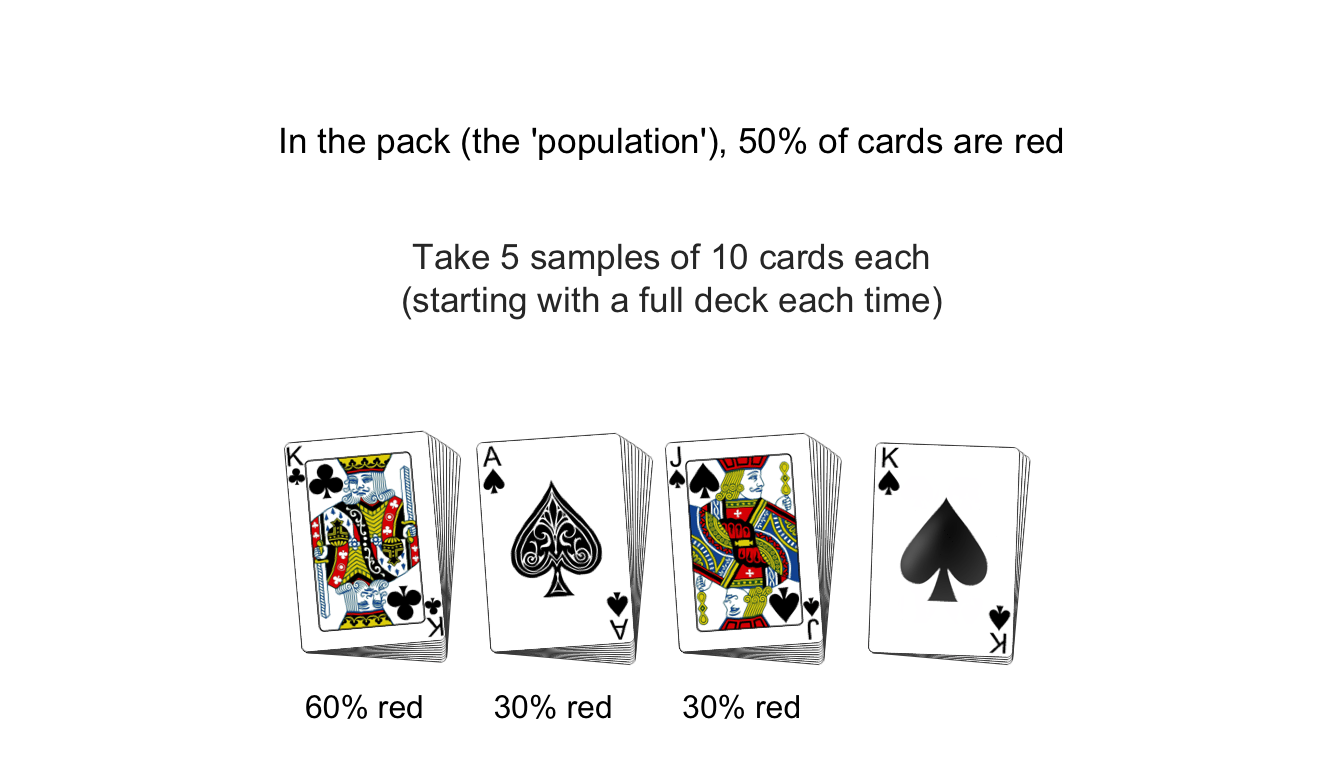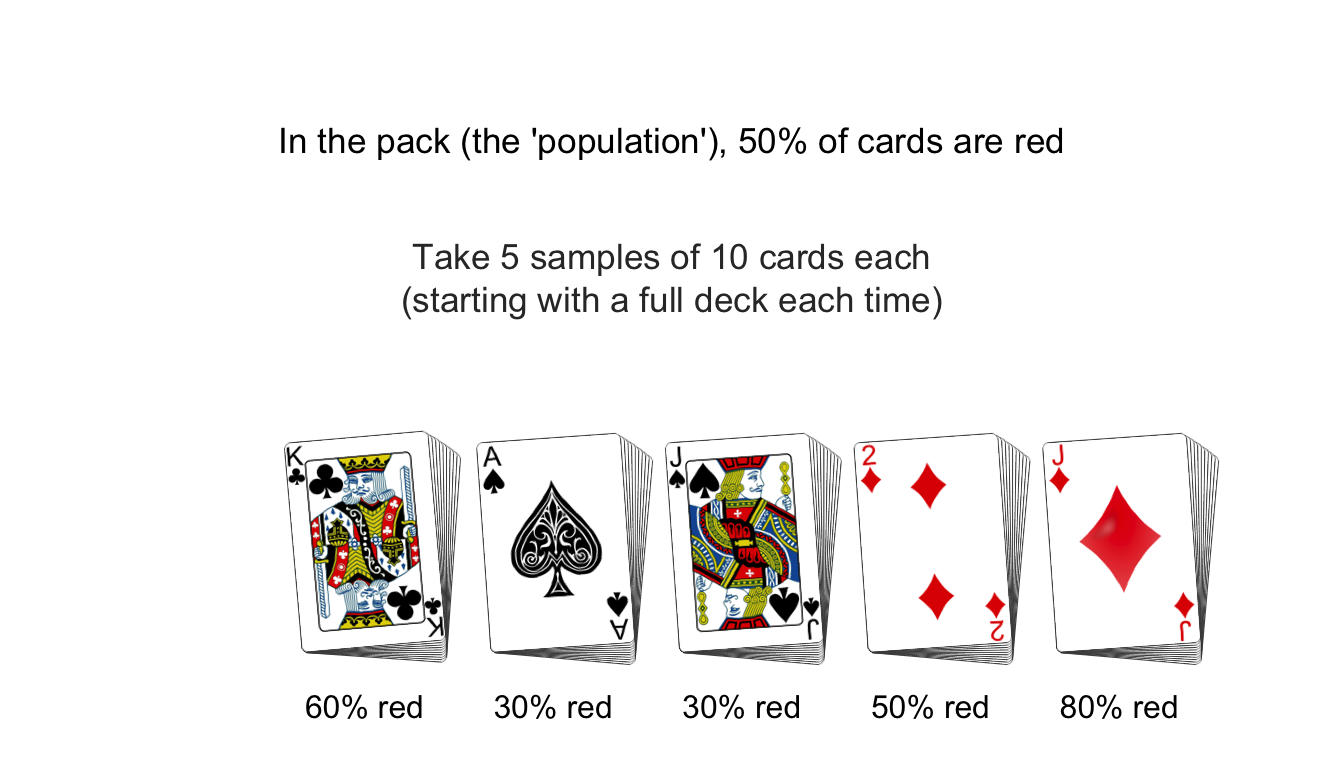
Consider a fair pack of cards (a population), where \(50\)% of cards are red. The percentage of red cards is not the same in every hand (every sample) of ten cards. This is a simple example of sampling variation.
Two questions concerning sampling in Section 6.2 were: which individuals should be in the sample, and how many individuals should be in the sample. The first question addresses the accuracy of using a sample value to estimate a population value. The second addresses the precision with which a population value is estimated using a sample. An estimate that is not accurate is called biased (Definition 4.31).
Precision refers to how similar the sample estimates from different samples are likely to be to each other (that is, how much variation is likely in the sample estimates).
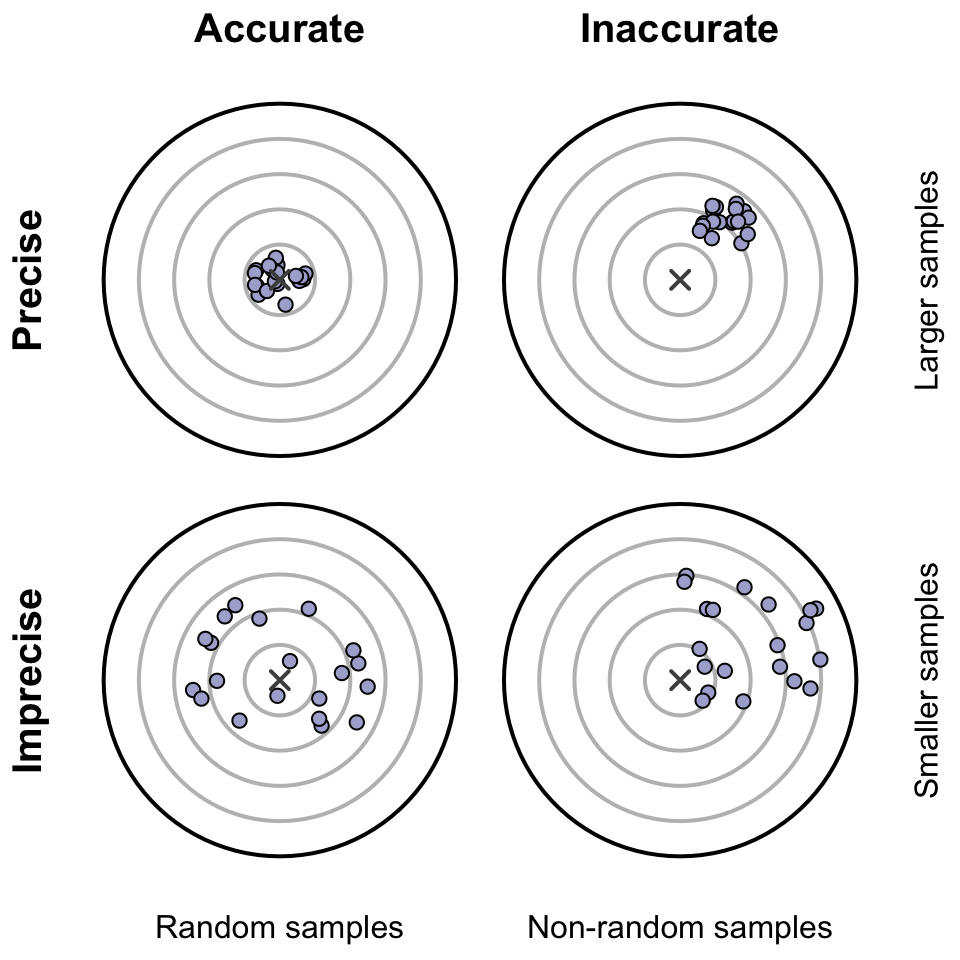
Large samples are more likely to produce precise estimates, but they may or may not be accurate estimates. Similarly, random samples are likely to produce accurate estimates, but they may or may not be precise. As an analogy, consider an archer aiming at a target. The shots can be accurate, or precise, or (ideally) both (Figure 6.10).
Four archery targets arranged in a 2×2 grid. Top-left: precise and accurate (shots clustered at centre). Top-right: precise but inaccurate (shots clustered off-centre). Bottom-left: imprecise but accurate (shots spread around centre). Bottom-right: imprecise and inaccurate (shots spread off-centre). Labels indicate: precise/imprecise on left axis, accurate/inaccurate on top, larger/smaller samples on right, random/non-random samples on bottom.
Figure6.10.Precision and accuracy: each dot indicates where a shot at the target lands, and is like a sample estimate of the population value (shown by the central \(\times\)).
The answer obtained from the sample will be inaccurate because the sample is not representative of all Canadians. Since the sample is large, the answer will give a precise answer but to a different question: “What is the average age of Canadian school children?”
One key to obtaining accurate estimates about the population from the sample is to ensure that the sample faithfully represents the population. So, how is such a sample selected from the population?
The individuals selected for the sample can be chosen using either random sampling or non-random sampling. The word random here has a specific meaning that is different from how it is often used in everyday use. It does not mean “haphazard”, “erratically” or “picking individuals as aimlessly as I can”.
The results obtained from a random sample are likely to generalise to the population from which the sample is drawn; that is, random samples are likely to produce externally valid and accurate studies.
A pot of soup can be tested randomly or non-randomly. If the soup is stirred (randomised), the small spoonful of soup can be tasted to obtain an overall impression. However, an overall impression is not obtained from a non-random sample (i.e., a non-stirred pot of soup).
judgement samples. Individuals are selected based on the researchers’ judgement (possibly unconsciously), perhaps because the individuals are (or may appear) agreeable, supportive, easily accessible, or helpful. For example, researchers may select rats that are less aggressive, or plants that are accessible, or people that look approachable.
convenience samples. Individuals are selected because they are convenient for the researcher. For example, researchers may study beaches that are nearby, or use their friends for a study.
voluntary response (self-selecting) samples. Individuals participate if they wish to. For example, researchers may ask people to volunteer to take a survey.
In non-random sampling, the individuals in the study are probably different from those not in the study. That is, non-random samples are not likely to be externally valid.
Researchers may use a non-random sample intentionally (e.g., to deceive) which is unethical, or unintentionally (e.g., accidentally, or due to practicality (such as meeting budgets)). Ethically, a random (or somewhat representative sample; Section 6.6) should be used when possible.
Using a non-random sample means that the results probably do not generalise to the intended population: they probably do not produce externally valid or accurate studies.
Selecting a simple random sample requires a list of all members of the population, called the sampling frame, from which to select a sample. Obtaining the sampling frame is often difficult or impossible, and so finding a simple random sample is also difficult. For example, finding a simple random sample of wombats would require having a list and location of all wombats. This is absurd; other random sampling methods, like special ecological sampling methods (e.g., [62]), would be used instead.
Selecting a simple random sample from the sampling frame can be performed using random numbers (e.g., using random number tables, or websites like random.org).
For students in a large university course, is the average typing speed (in words per minute) the same for those aged under \(25\) (“younger”) and \(25\) or over (“older”)?
Suppose budget and time constraints mean approximately \(40\) students (out of \(441\)) can be selected for the study. The sampling frame is the list of all students enrolled in the course. Obtaining the sampling frame is feasible here; instructors have access to this information for grading.
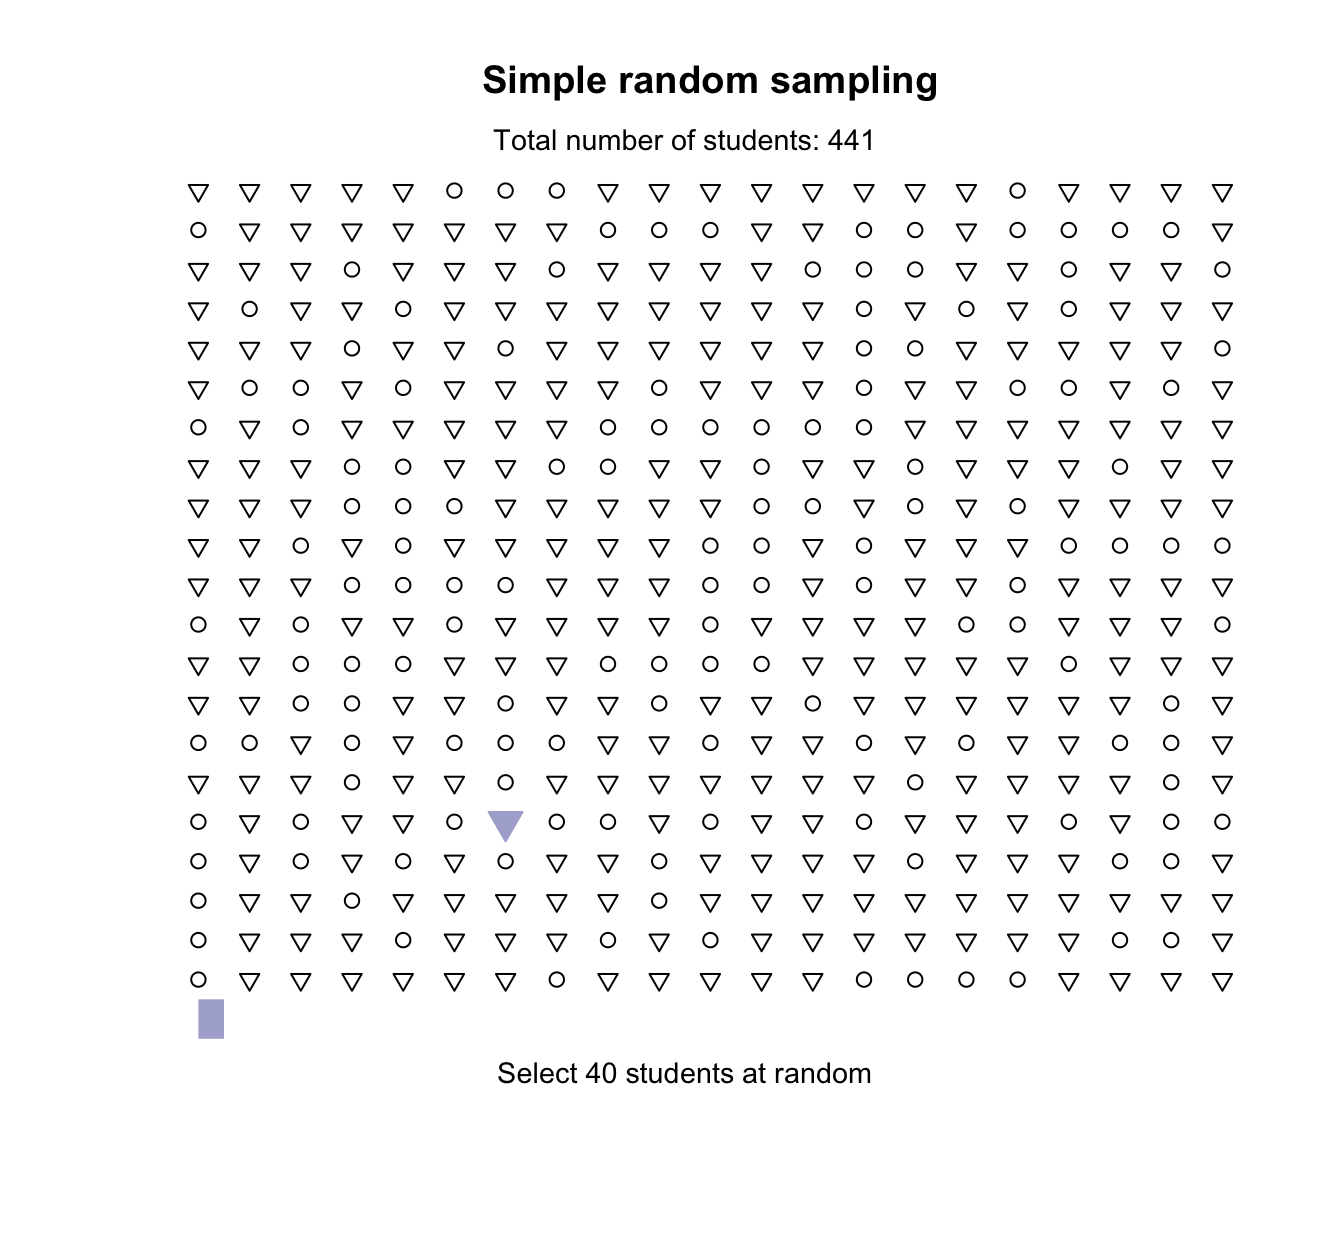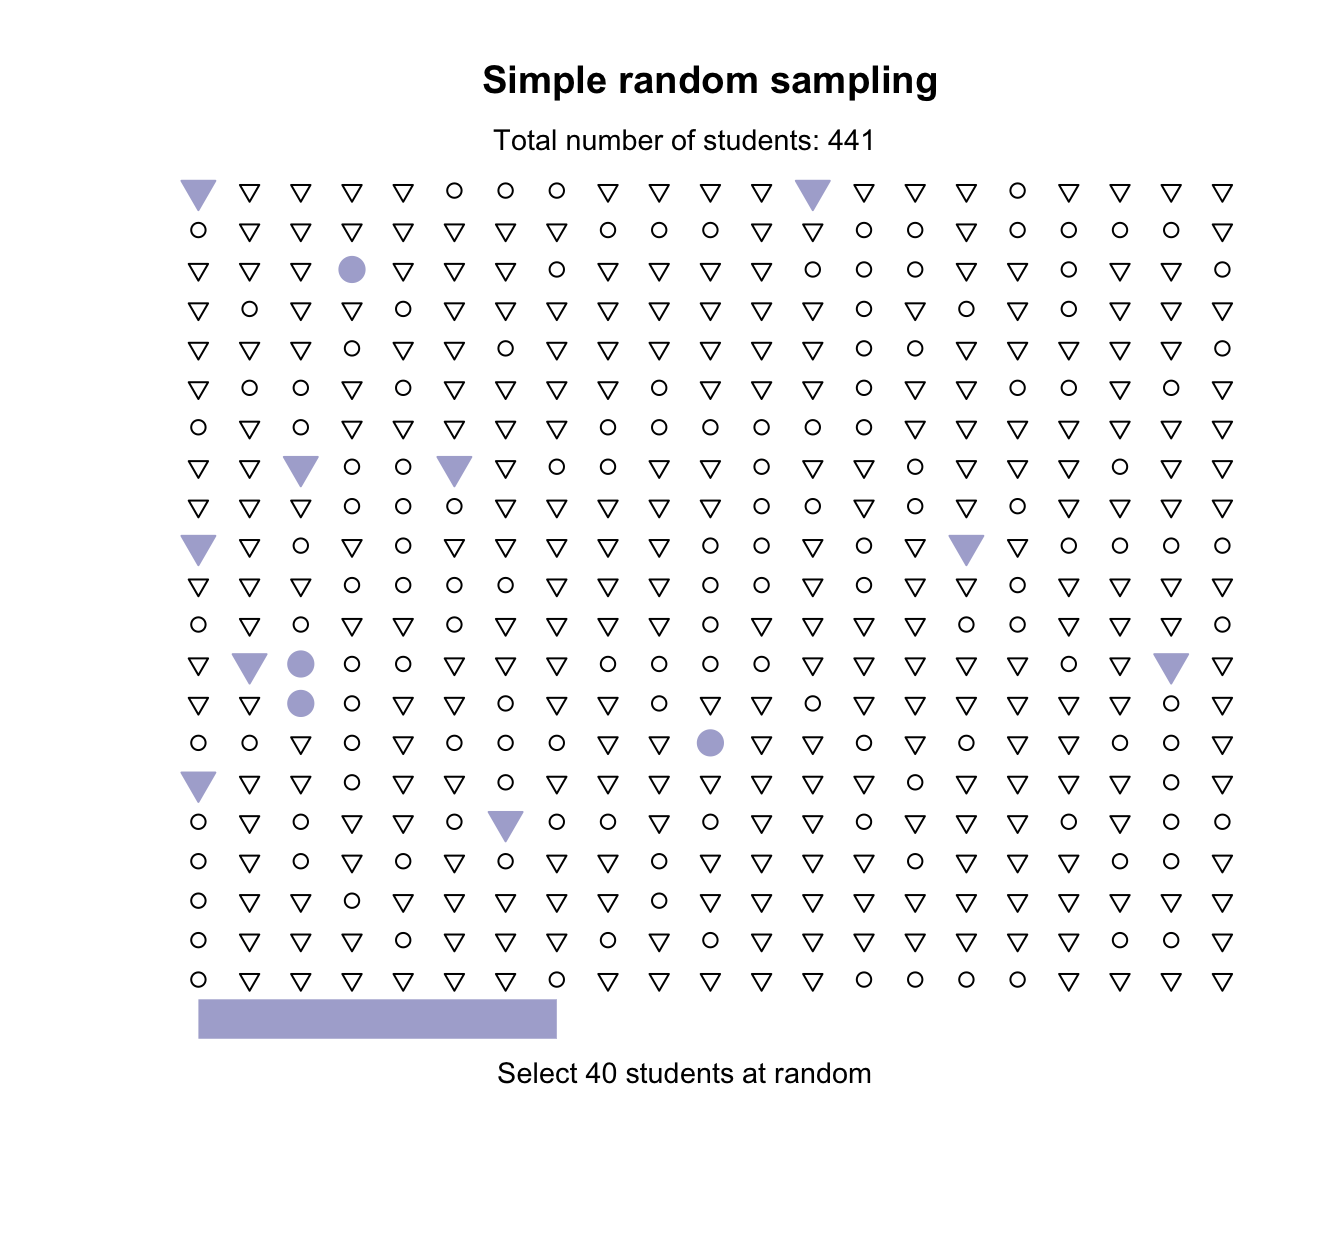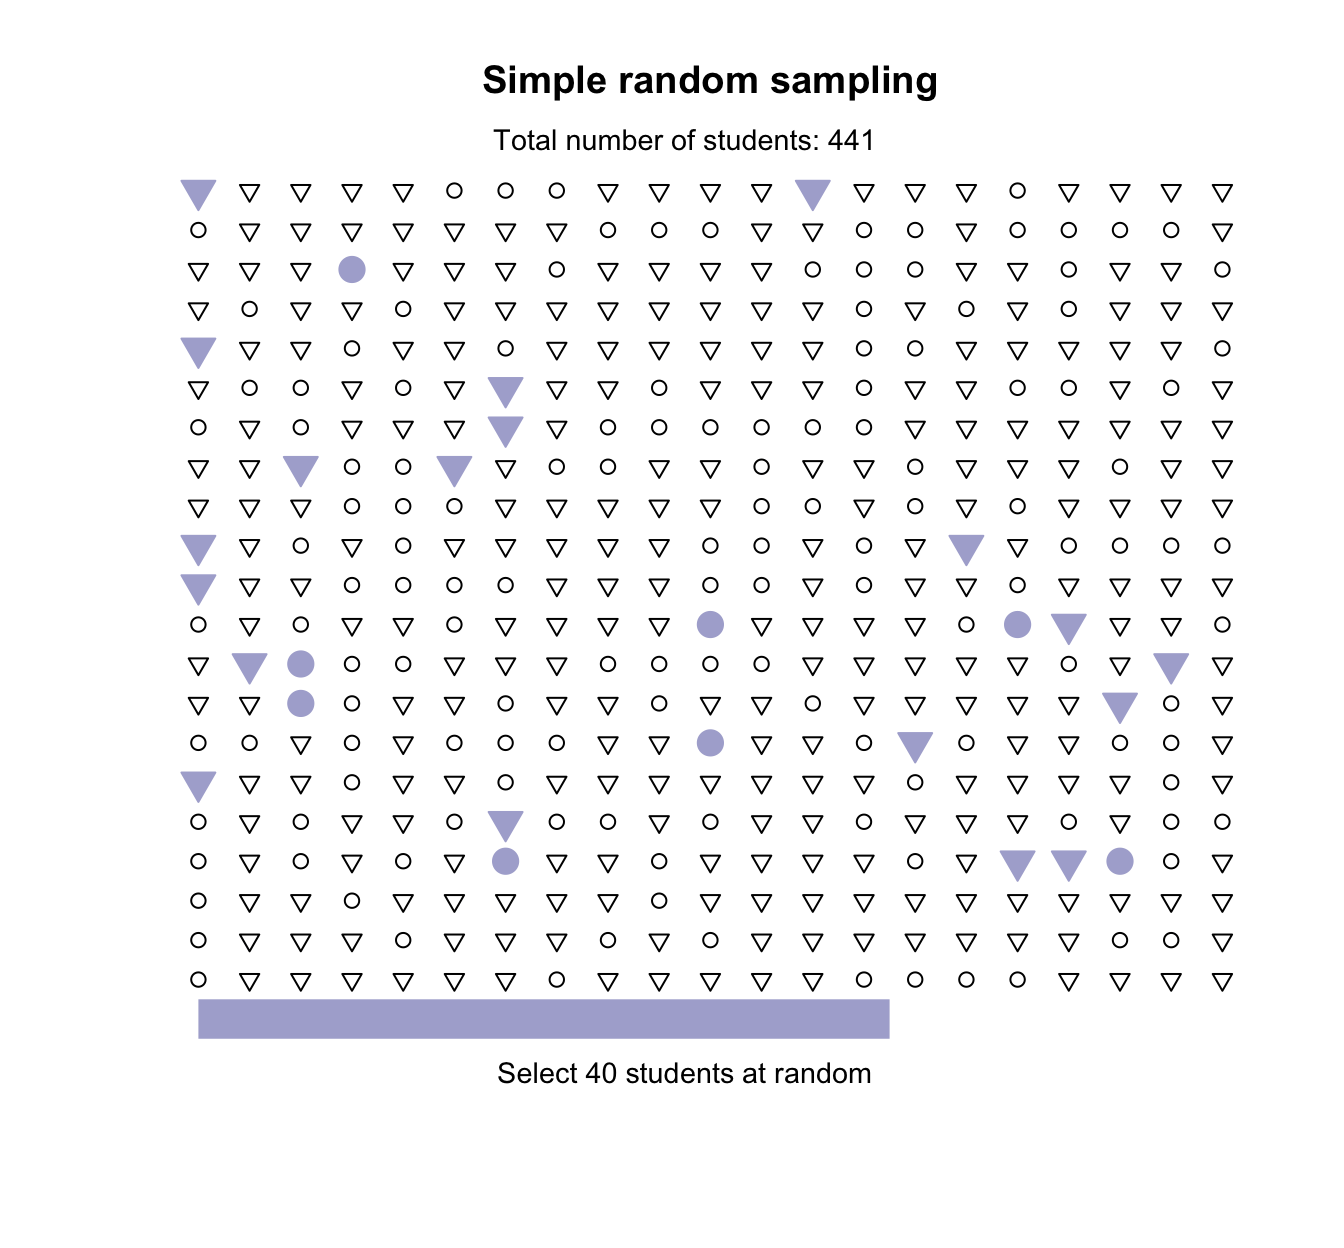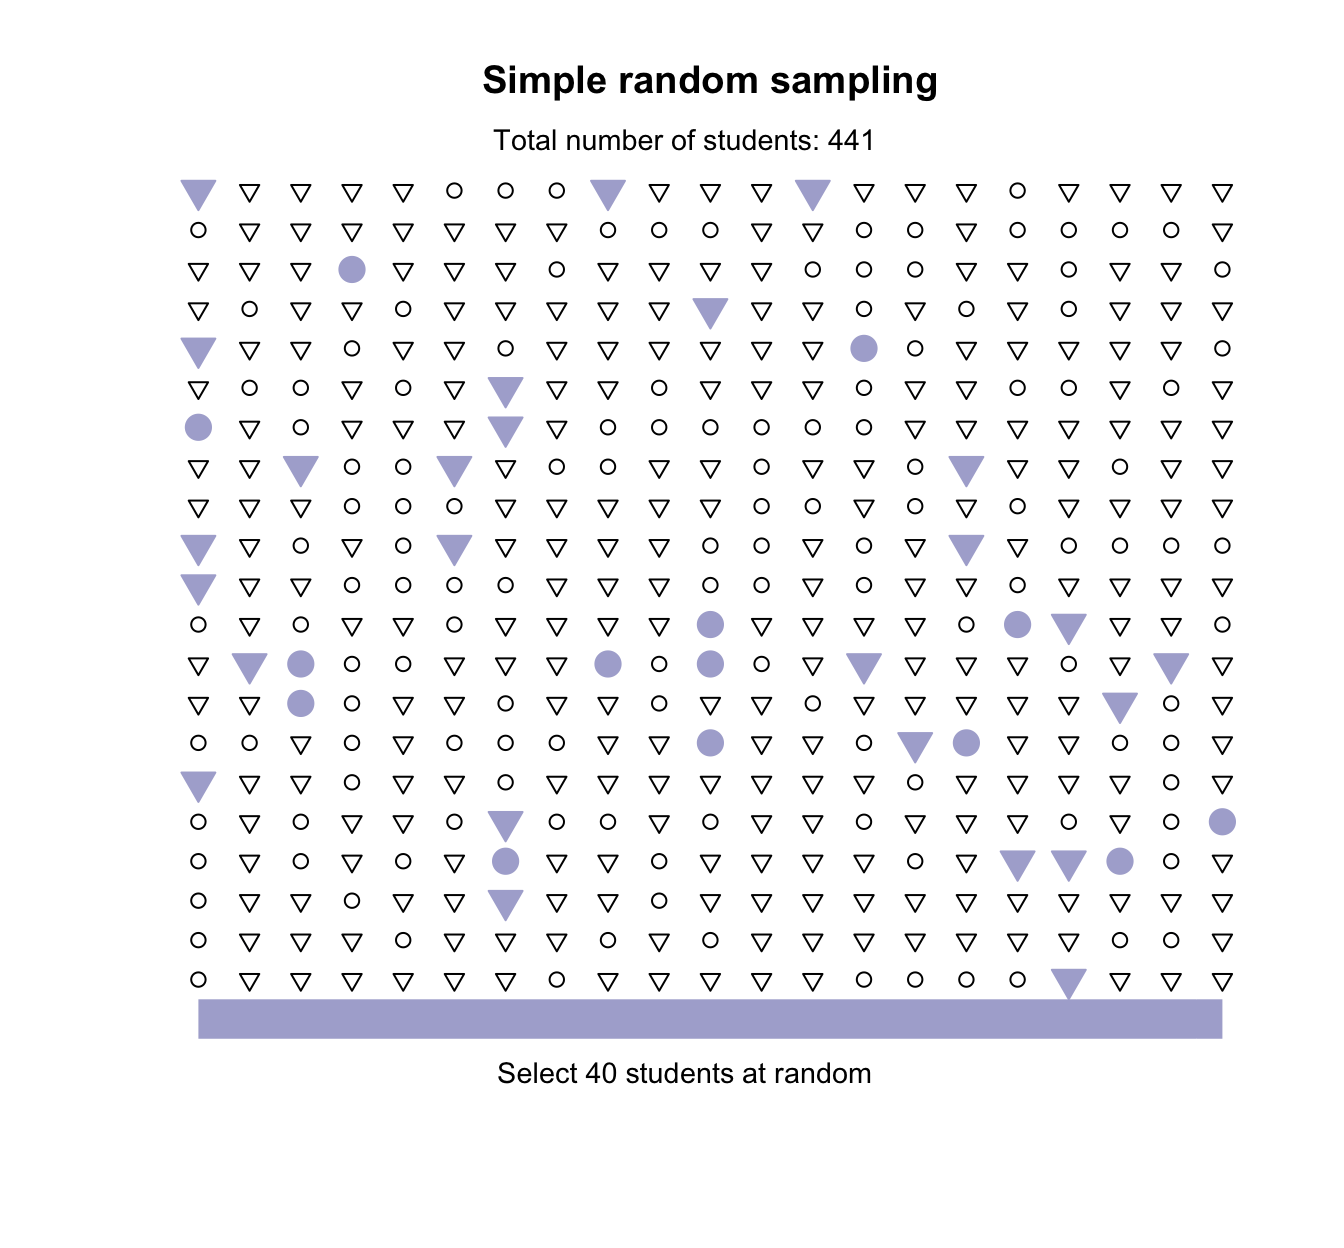
A simple random sample could be found using the course enrolment list, by first placing all \(441\) student names into rows of a spreadsheet (ordered by name, student ID, or any way). Then, using random numbers, \(40\) rows are selected at random (without repeating numbers) between \(1\) and \(441\) inclusive. For instance, when I used random.org the first few random numbers might be: 410, 215, 384, 158, 296.
Every student chosen using this method becomes part of the study. If a student could not be contacted or did not respond, more students could be chosen at random to ensure \(40\) students participated. By chance, the sample comprises \(15\) younger students and \(25\) older students.
In systematic sampling, the first case is randomly selected; then, more individuals are selected at regular intervals thereafter. In general, we say that every \(n\)th individual is selected after the initial random selection.
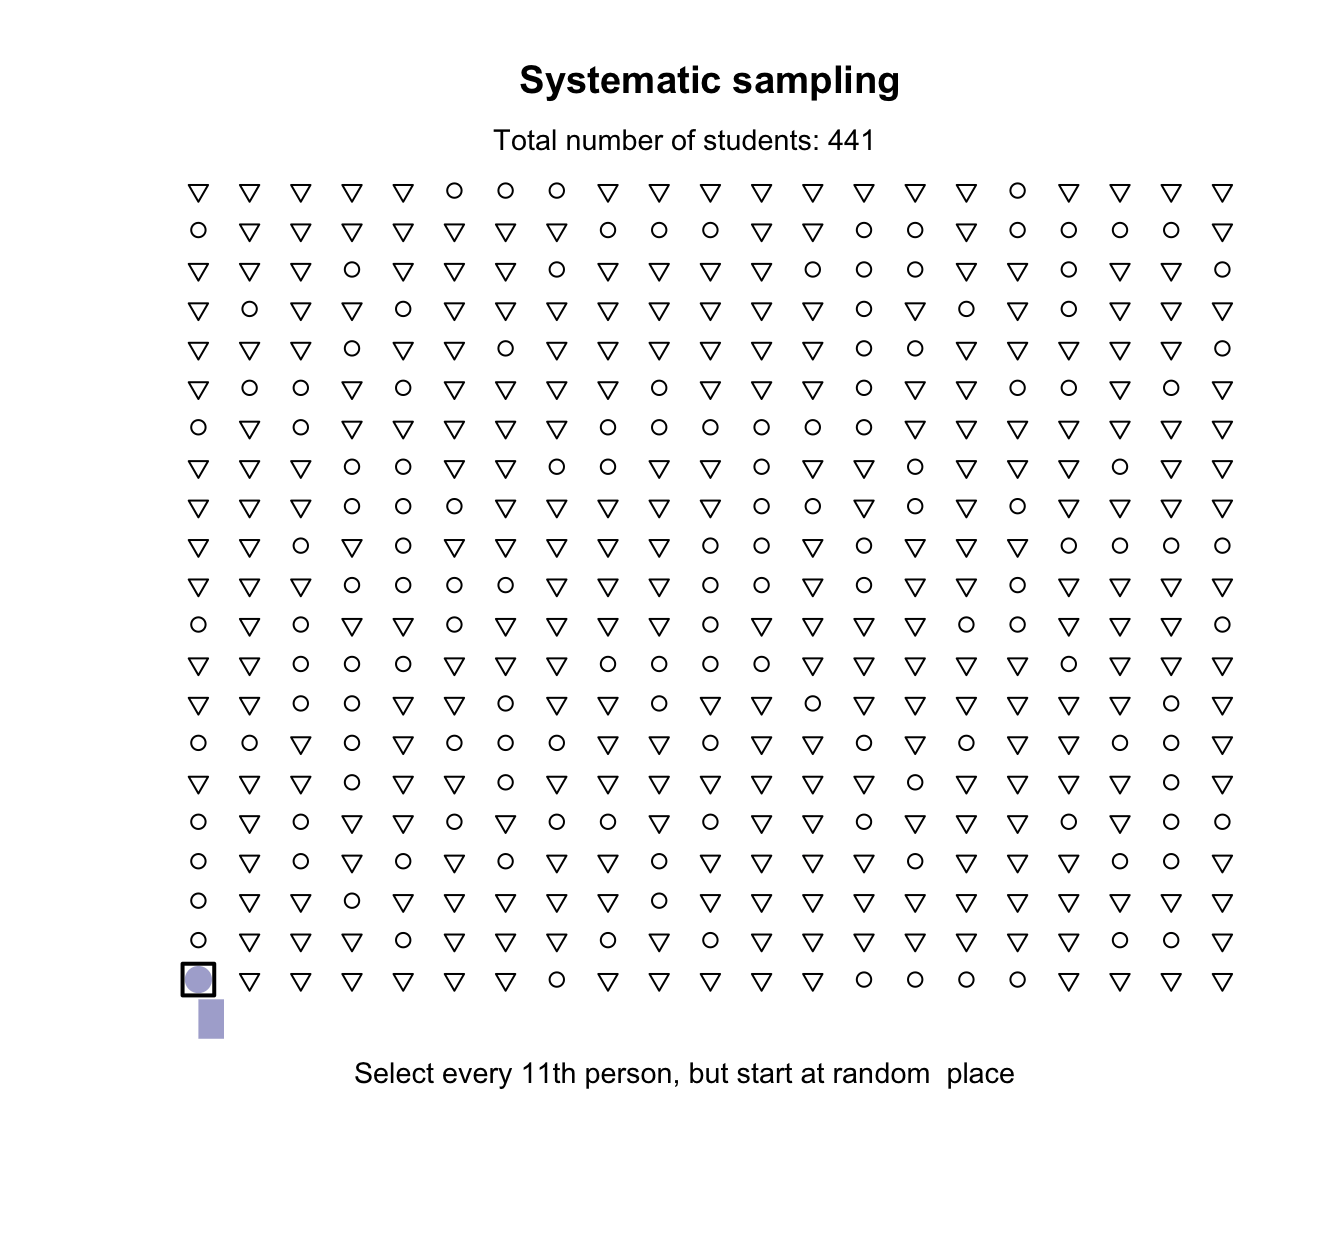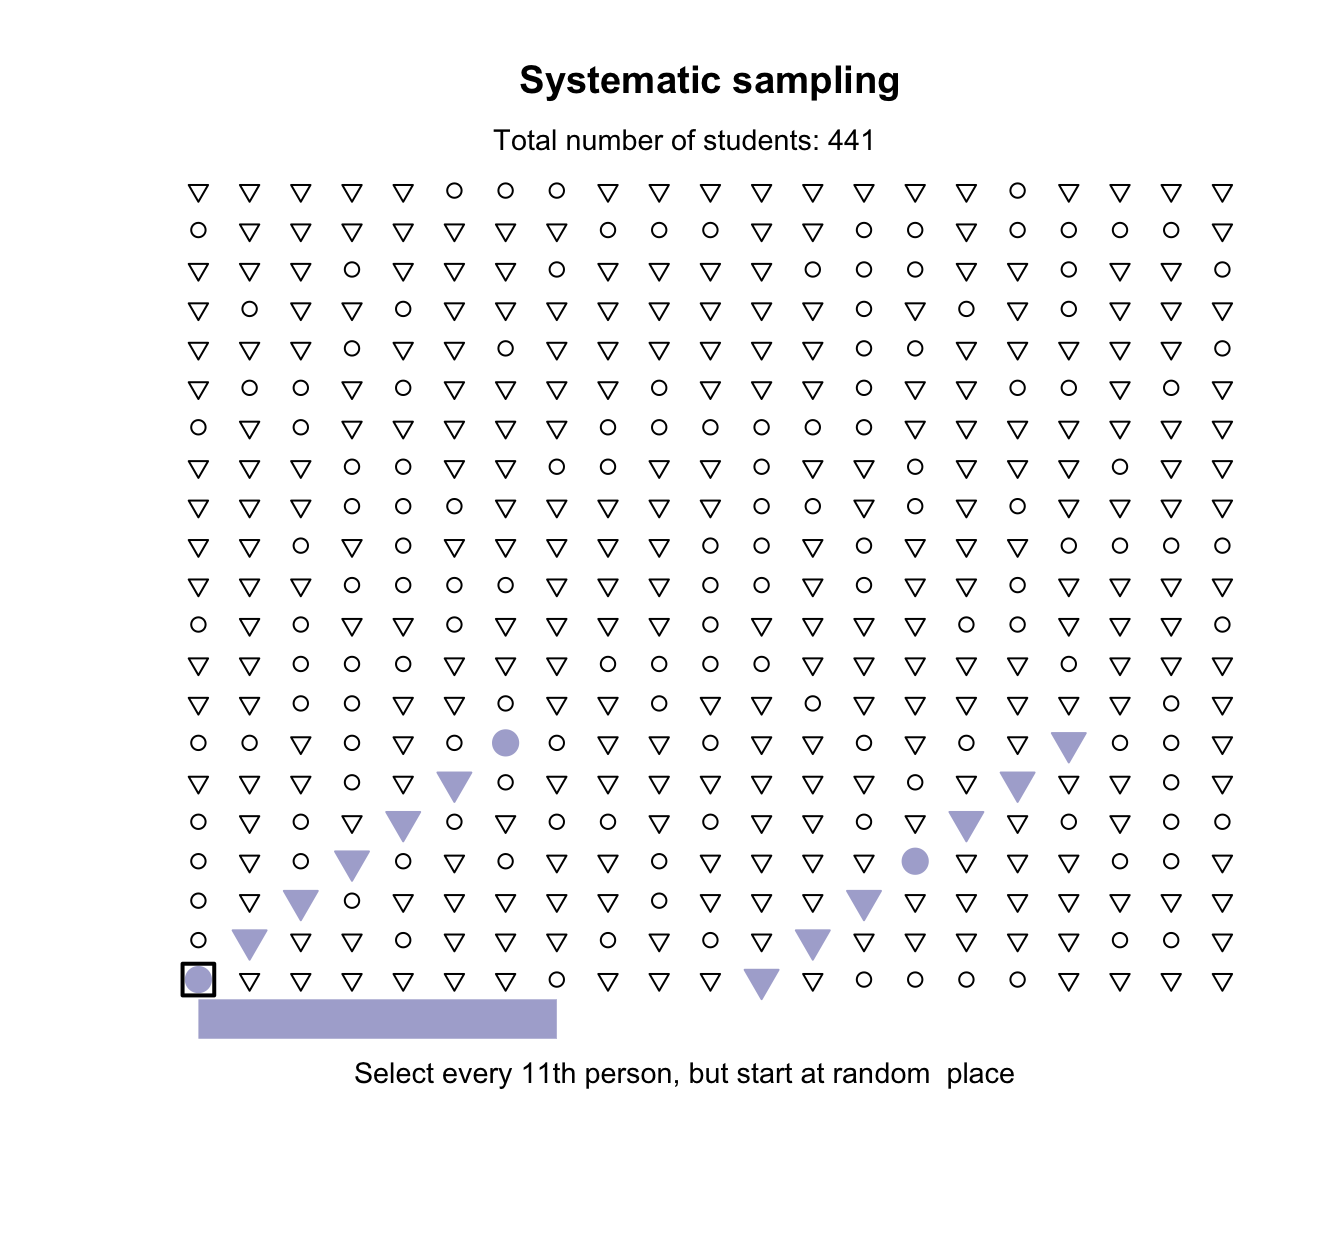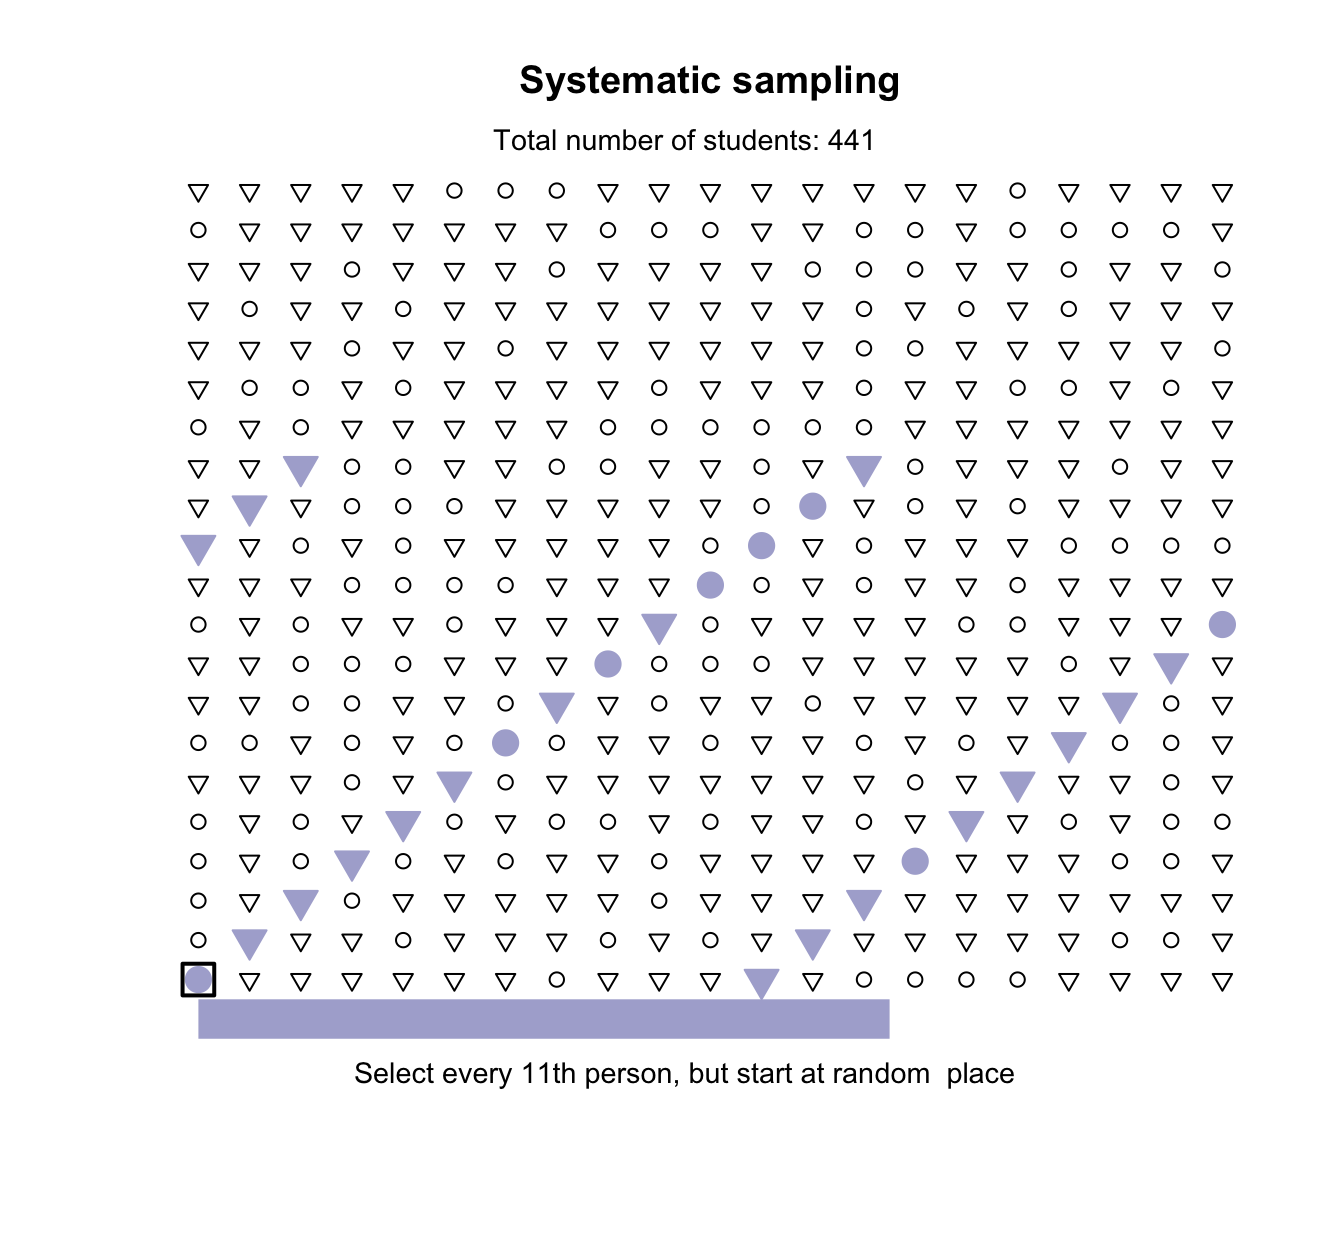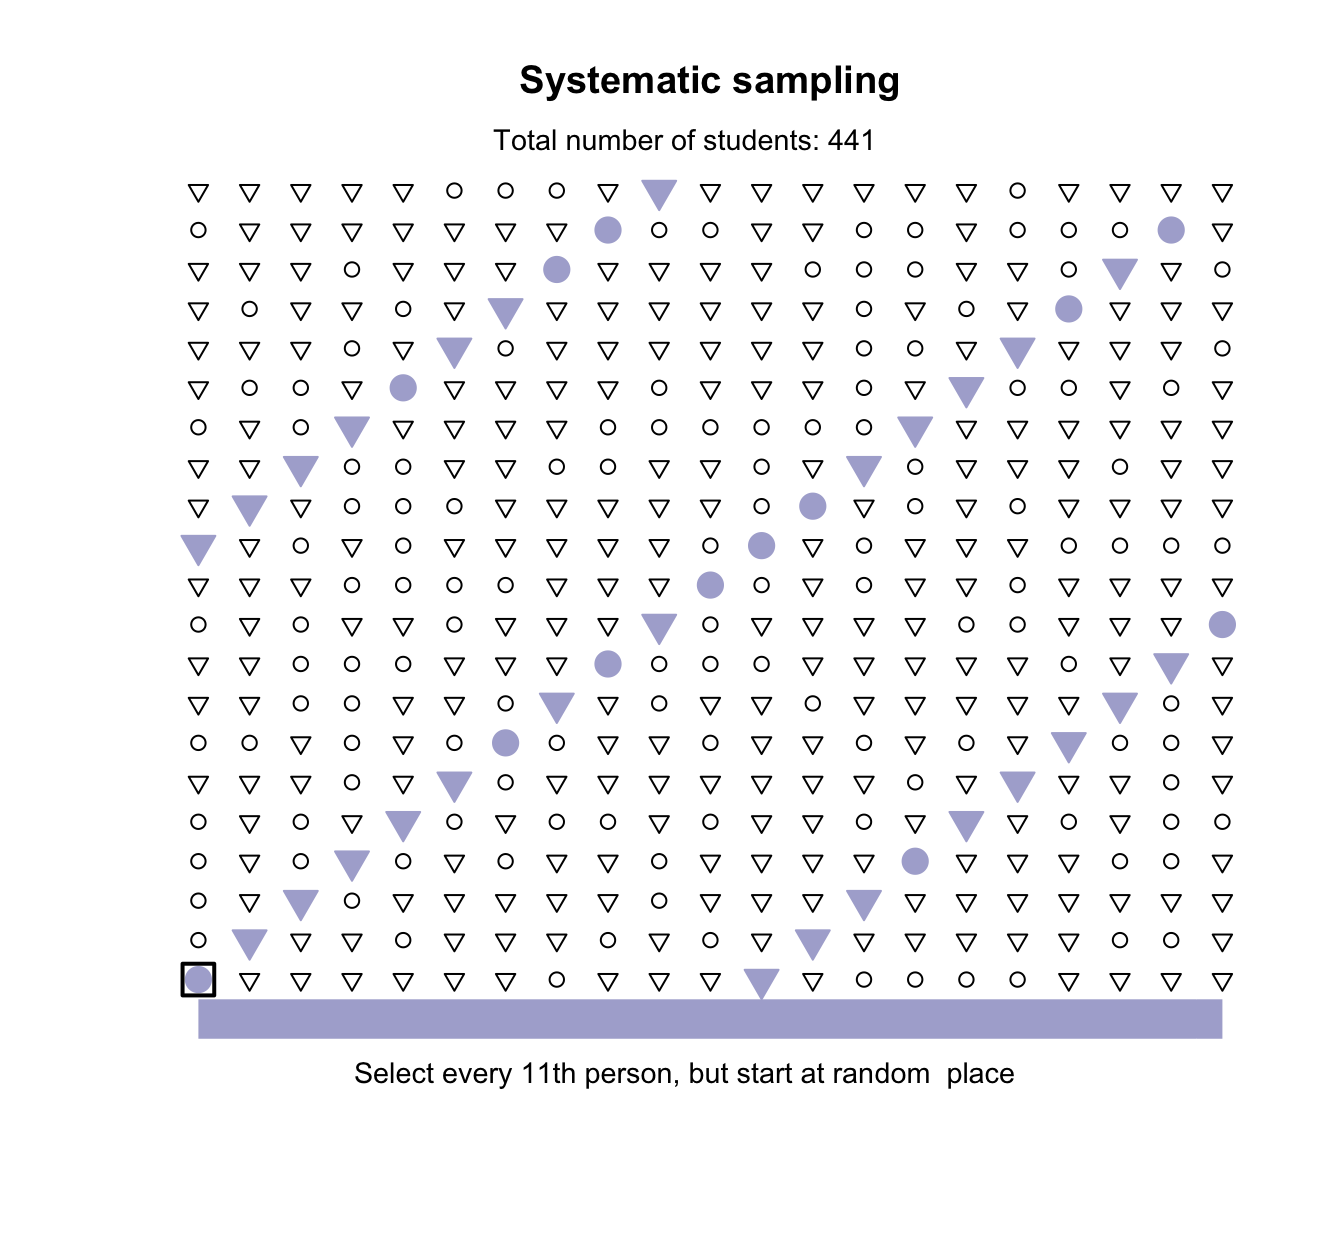
For the study in Example 3.5, a sample of \(40\) students in a course of \(441\) is needed. To find a systematic random sample, select a random number between \(1\) and \(441/40\) (approximately \(11\)) as a starting point; suppose the random number selected is \(9\text{.}\)
The first student selected is the \(9\)th person in the student list (which may be ordered alphabetically, by student ID, or other means). Thereafter, every \(441/40\)th person, or \(11\)th person, in the list is selected: people in rows \(9\text{,}\)\(20\text{,}\)\(31\text{,}\)\(42\text{,}\) and so on. By chance, the sample comprises \(17\) younger students and \(23\) older students.
Care needs to be taken when using systematic samples to ensure a pattern is not hidden. Consider taking a systematic sample of every \(10\)th residence on a long street. In many countries, odd numbers are usually on one side of the street, and even numbers usually on the other side. Selecting every \(10\)th house (for example) would include houses all on the same side of the street, and hence with similar exposure to the sun, traffic, etc.
[8] studied households in Quebec to determine if their hot water systems kept their water sufficiently hot to avoid Legionellae bacteria. They used a systematic random sample to select households to study (p. \(2\,361\)):
In stratified sampling, the population is split into a small number of large (usually similar) groups called strata, then cases are selected using a simple random sample from each stratum. Every individual in the population must be in one, and only one, stratum.
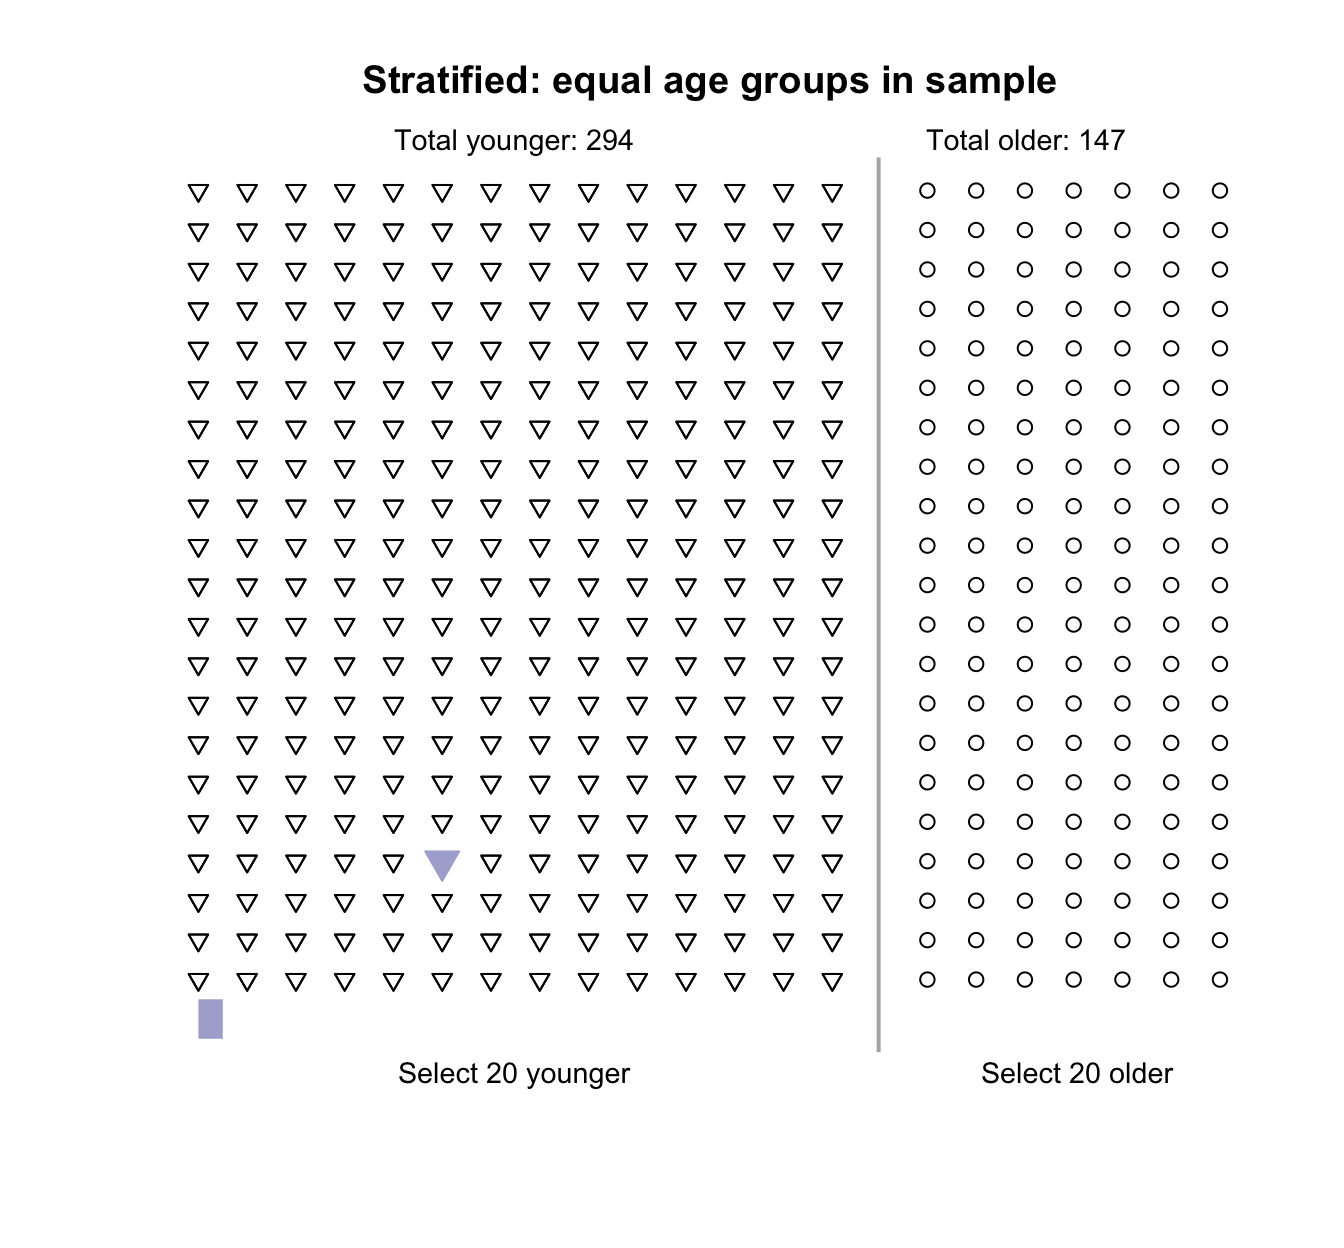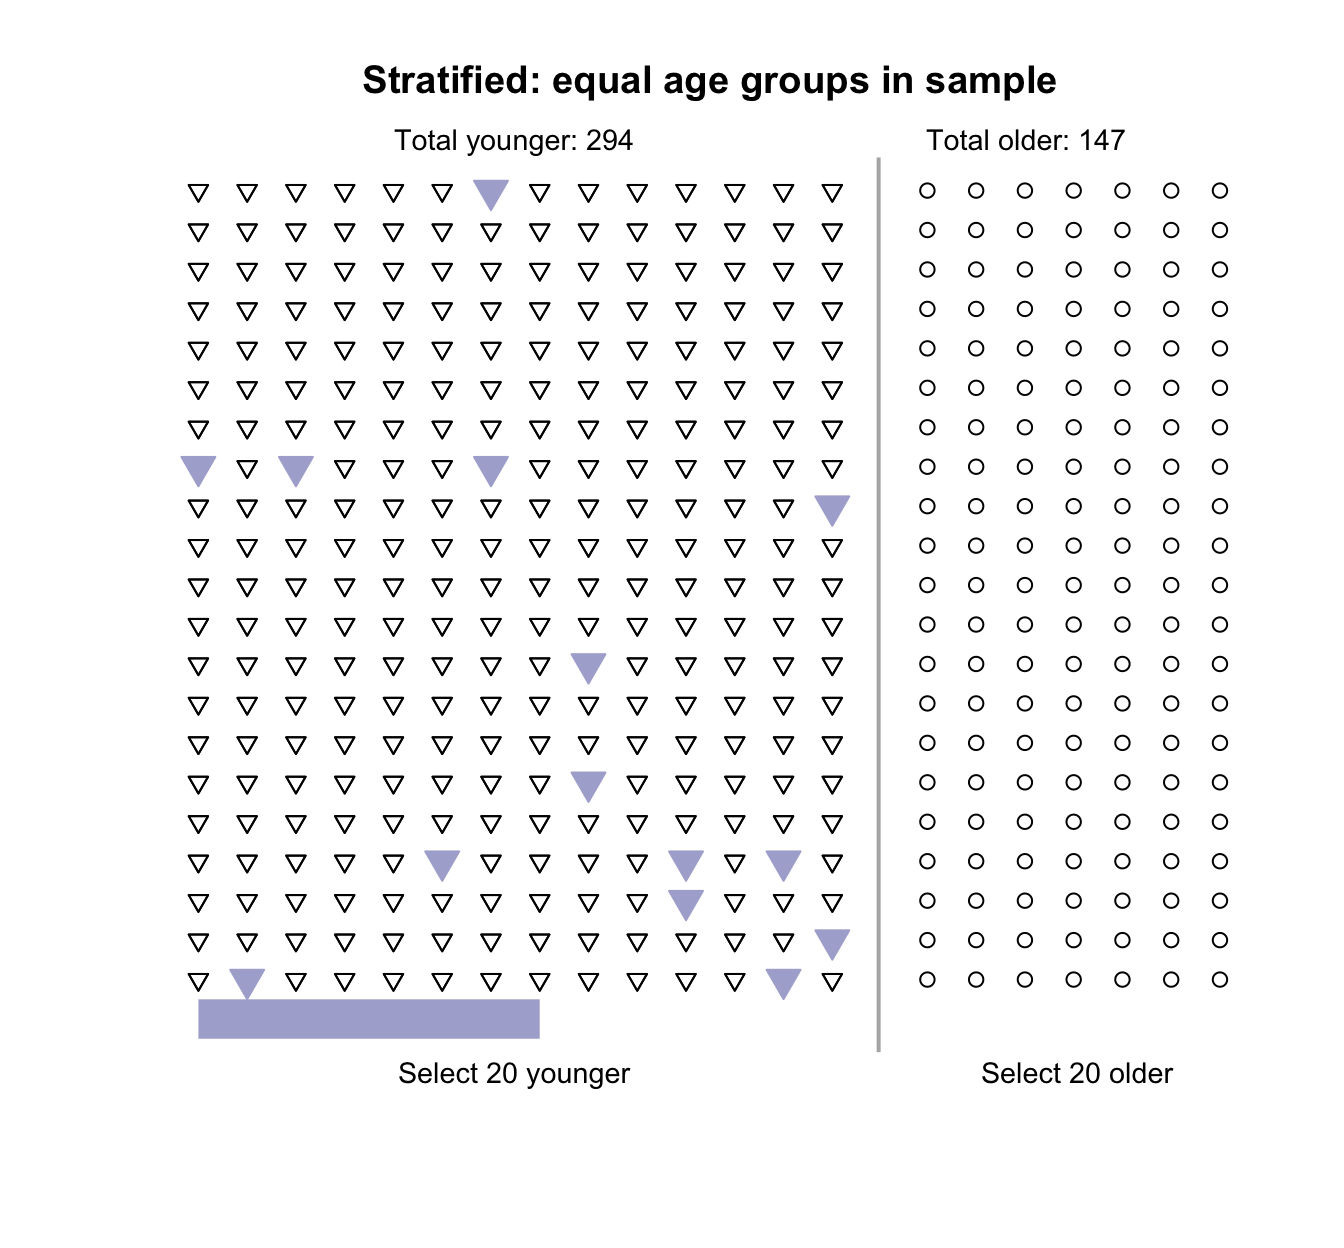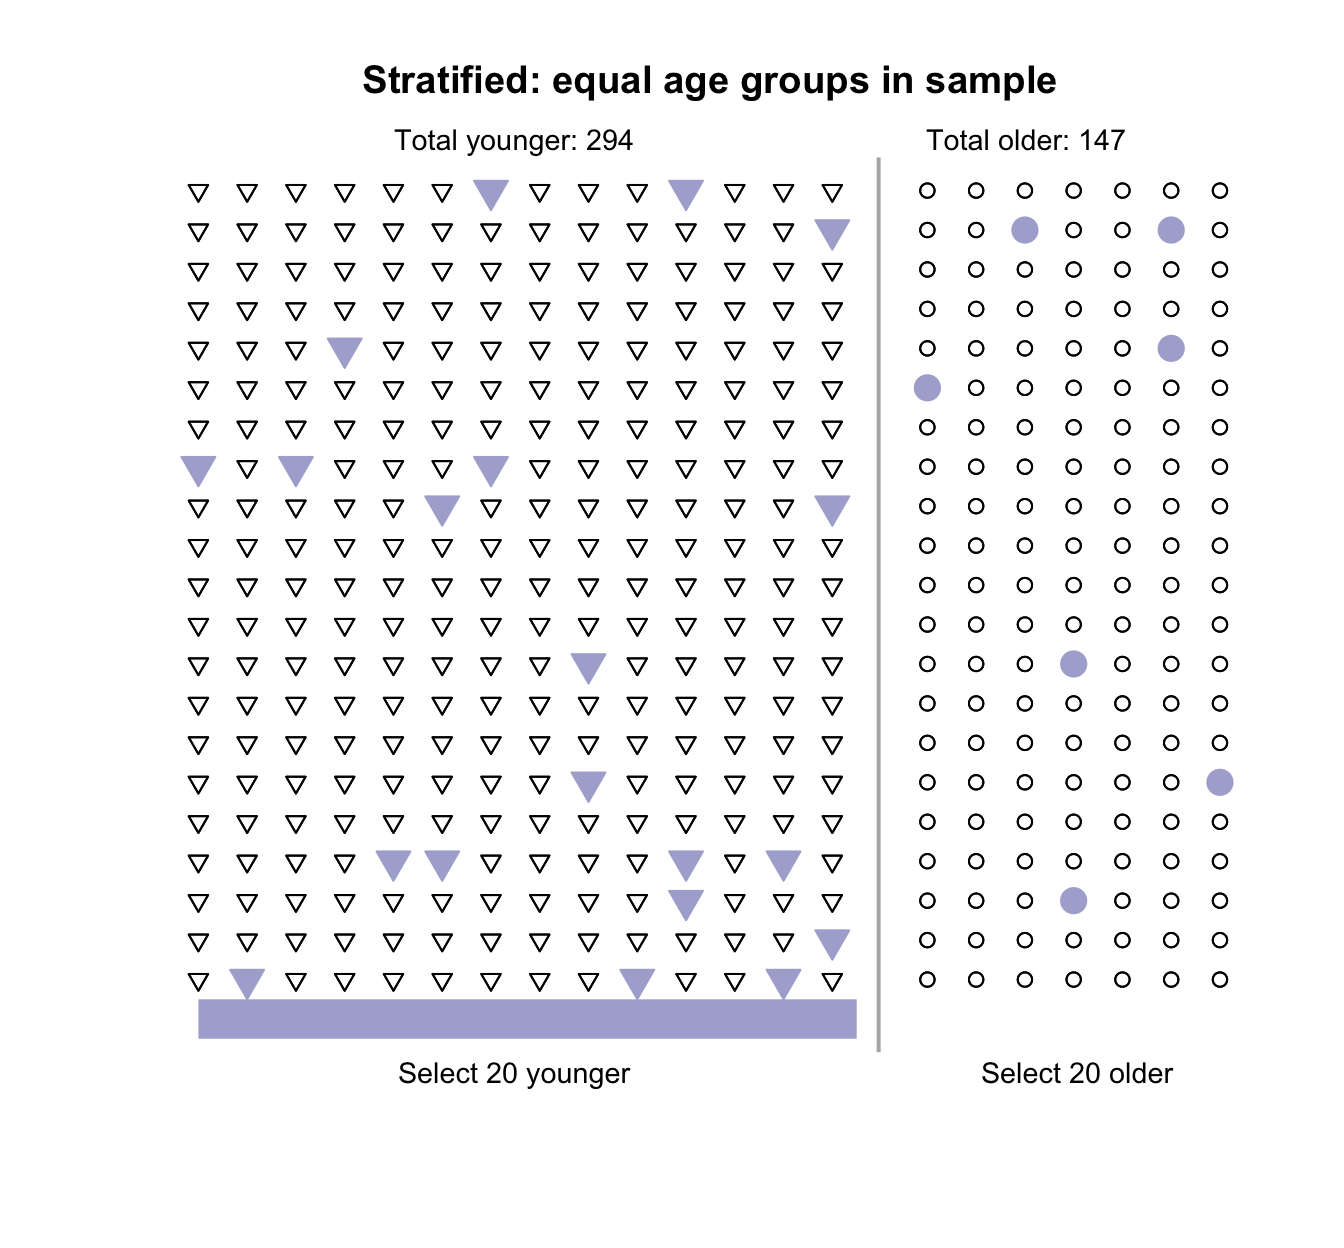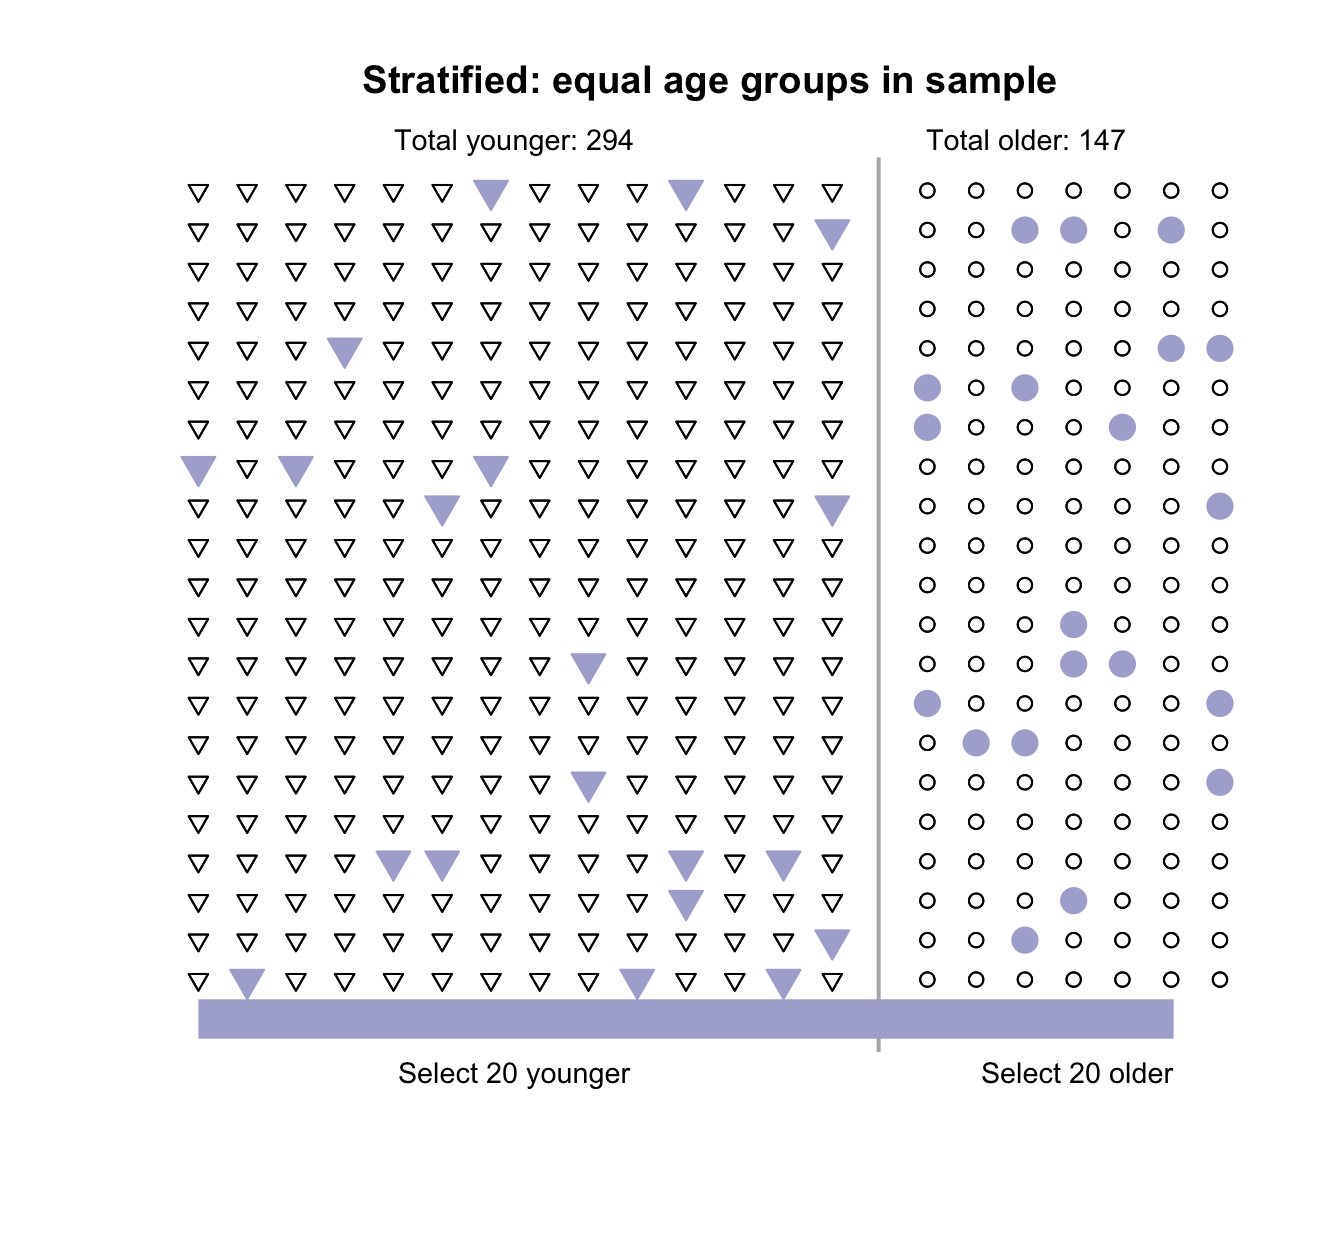
For the typing study in Example 3.5, \(20\) younger and \(20\) older students could be selected to obtain a sample of size \(40\text{.}\) The sample is stratified by age group of the person.
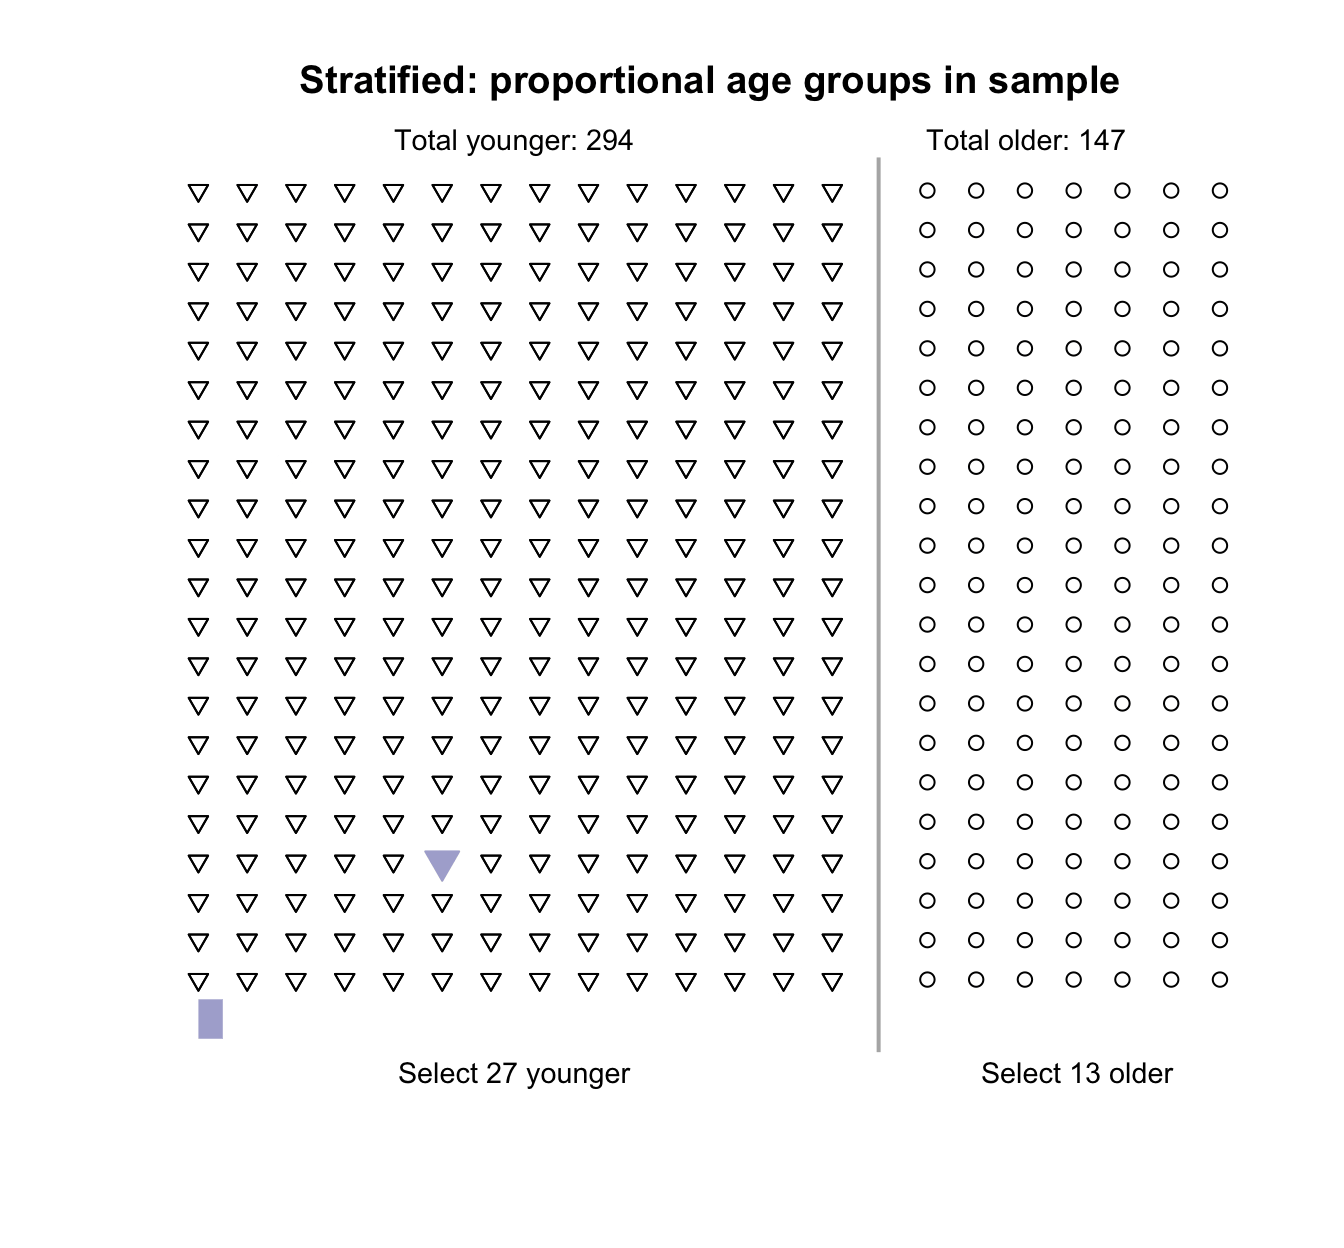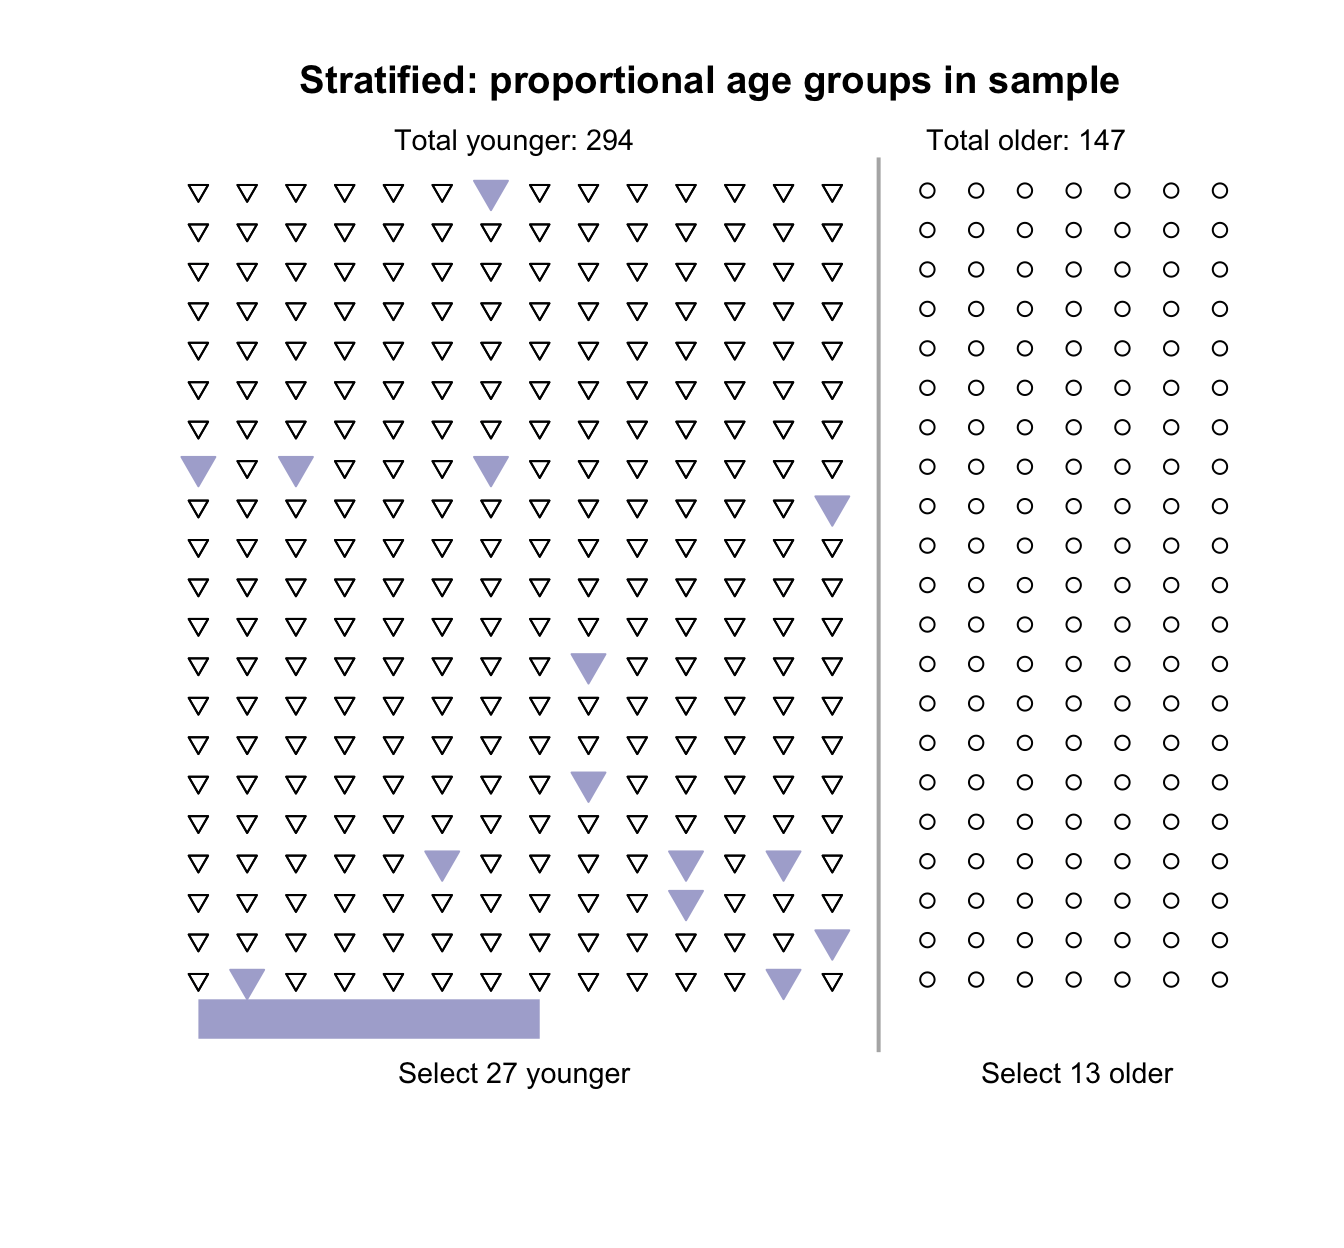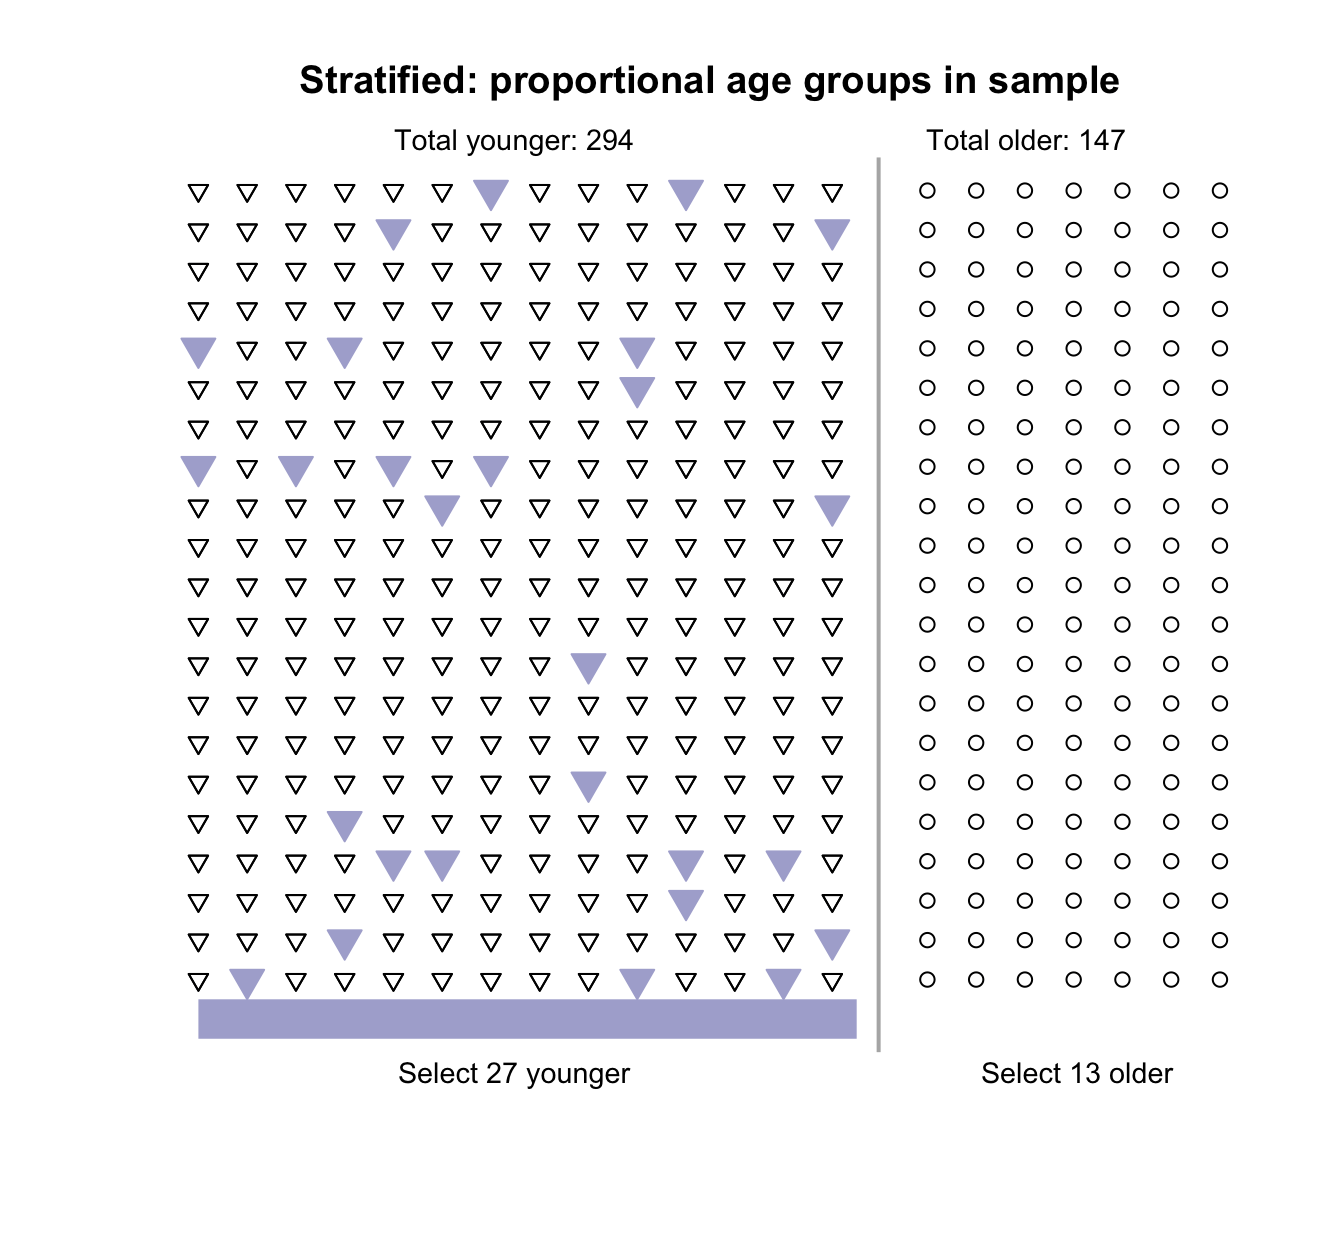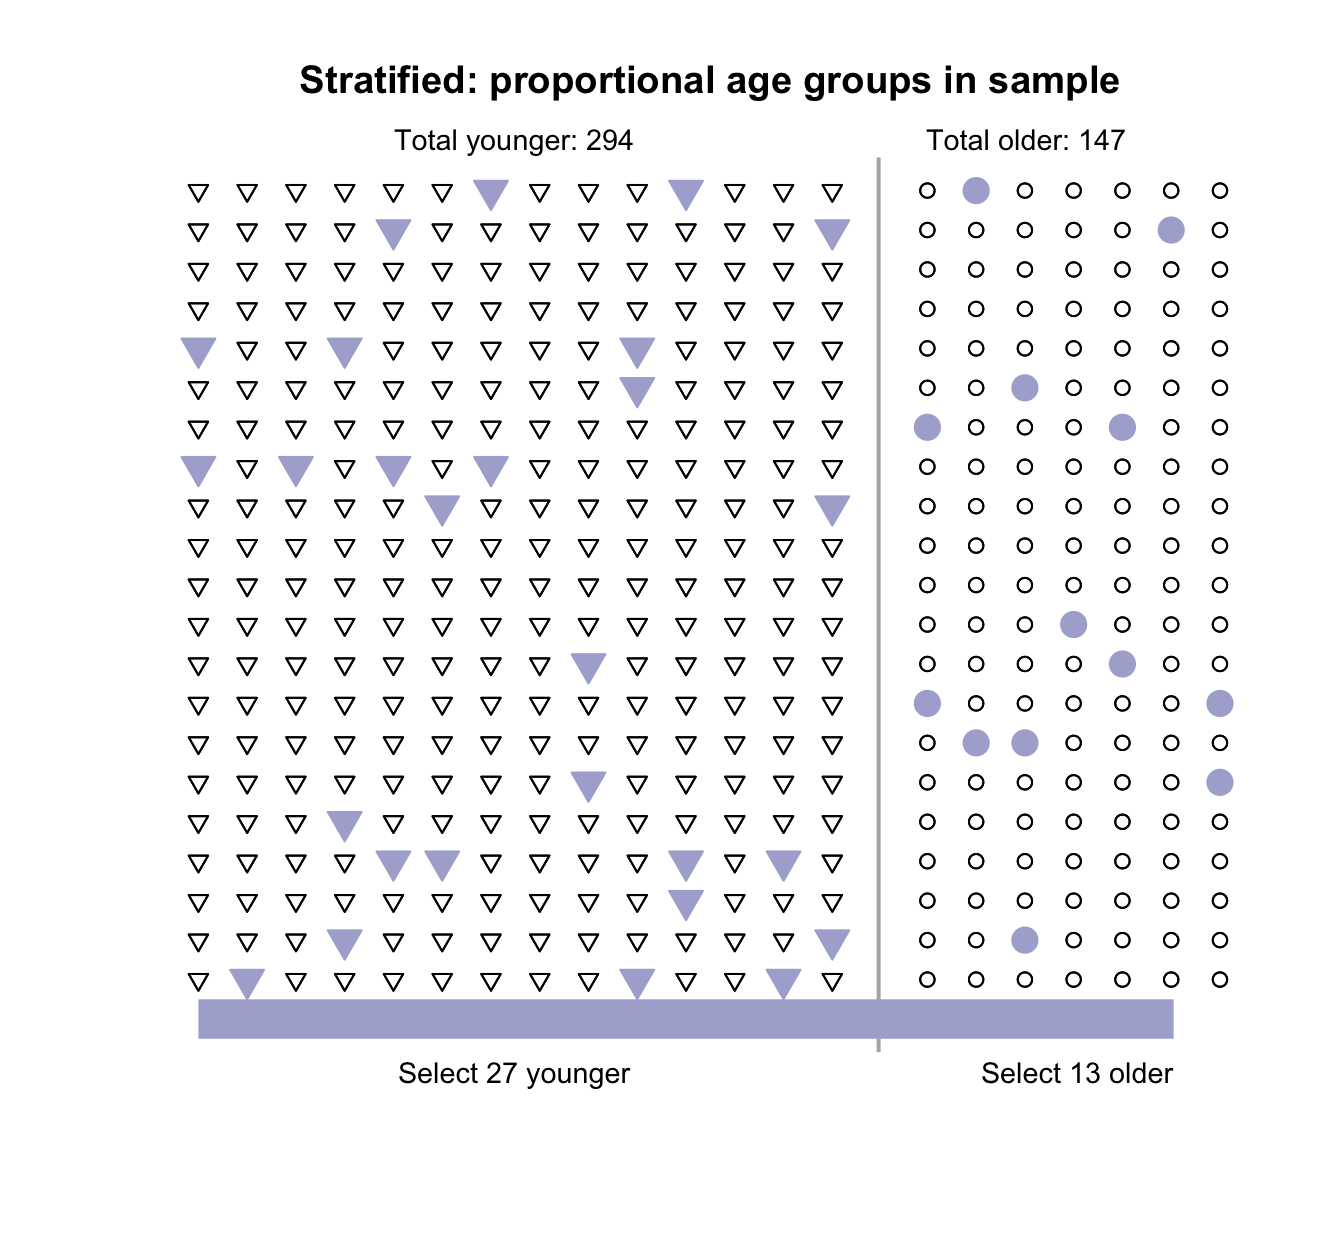
Since \(66.7\)% of the students are younger in the population, the sample could be selected so that two-thirds of the sample of size \(40\) (i.e., \(27\) students) were younger students. This is a proportional stratified sample.
Similarly, the second animation below shows how a stratified random sample of size \(40\) might be selected, by randomly selecting \(27\) younger and \(13\) older students.
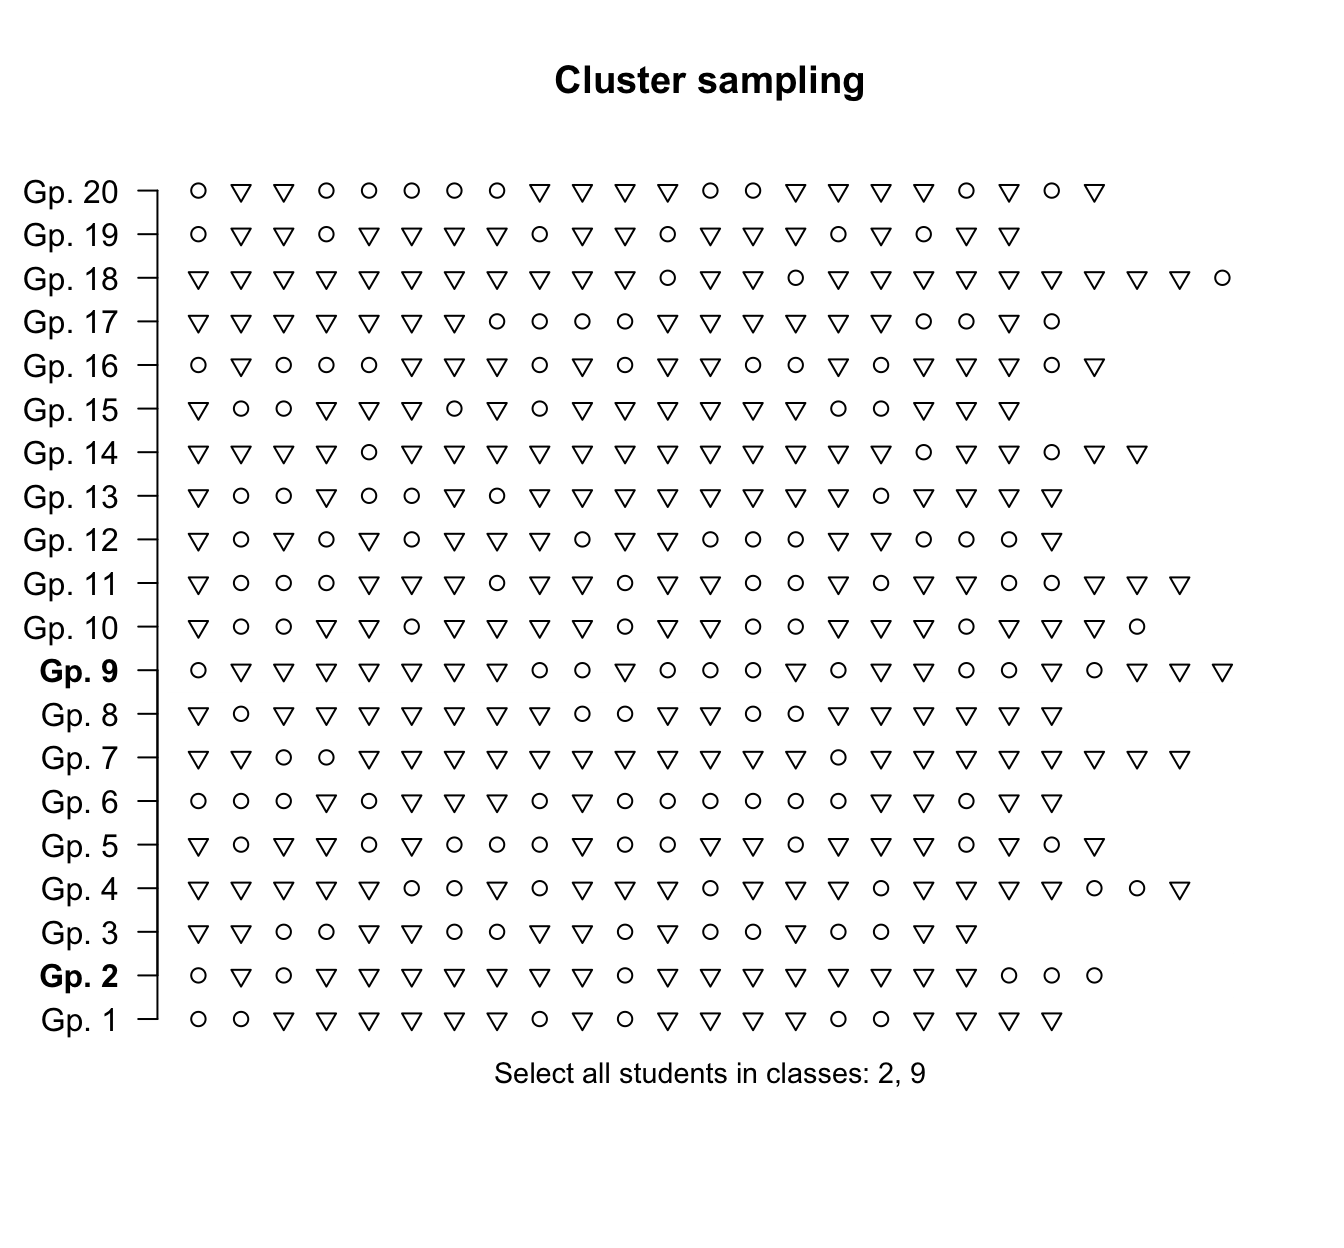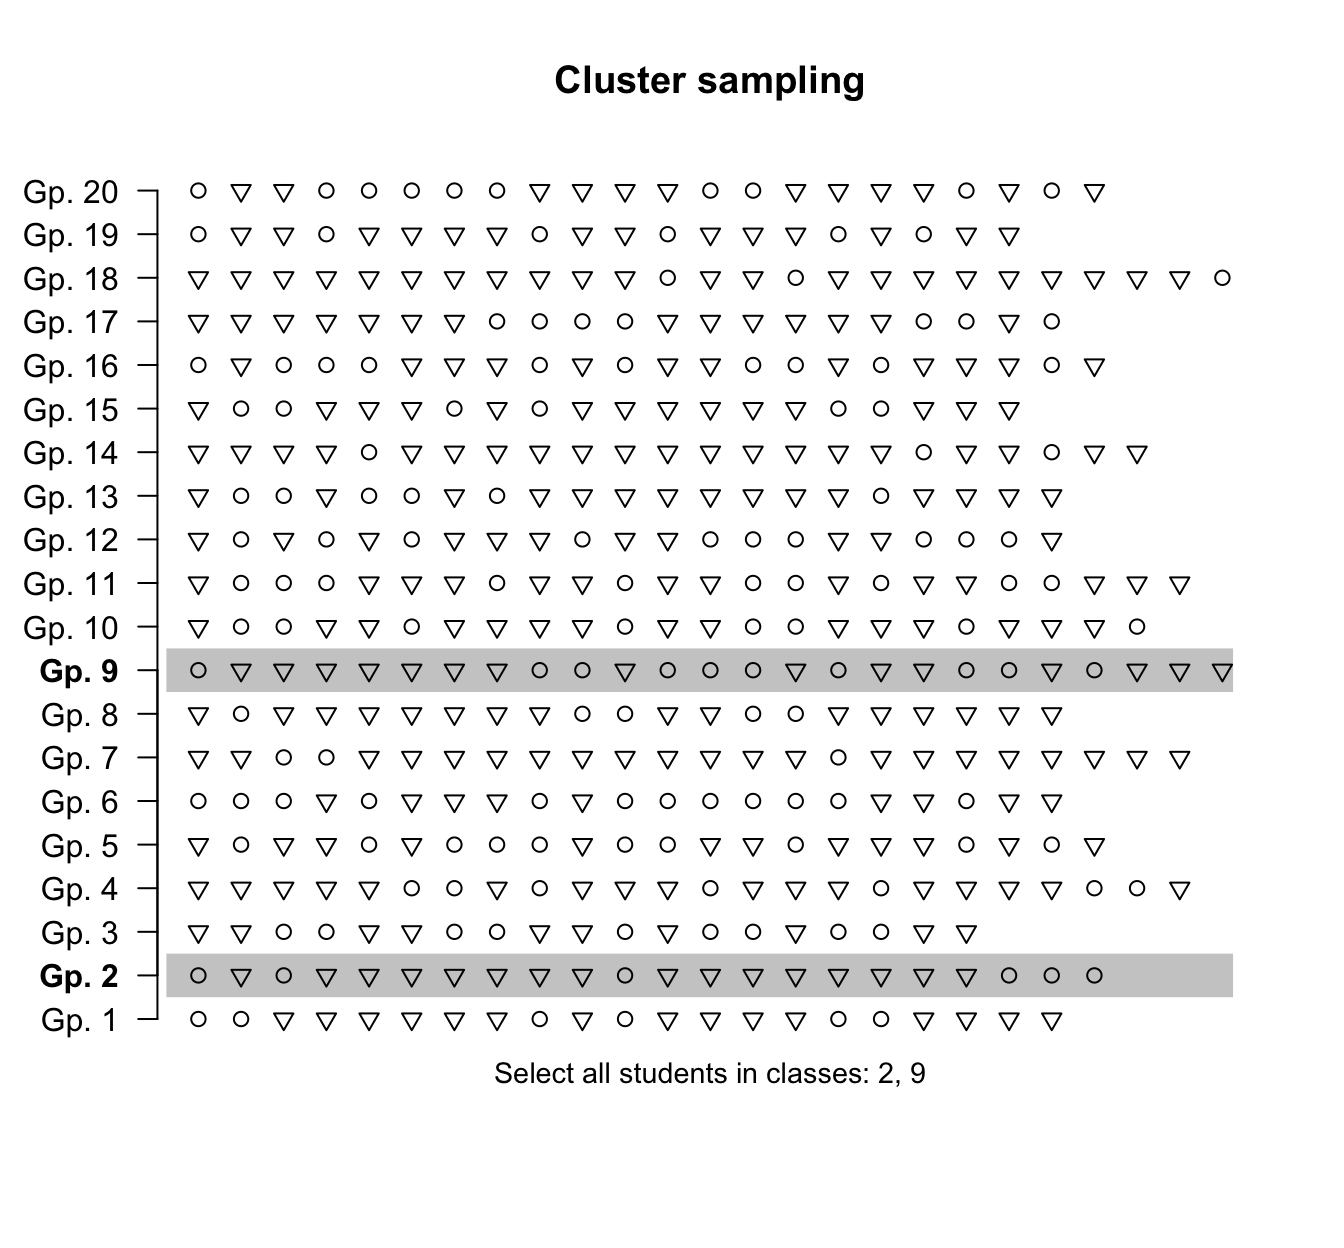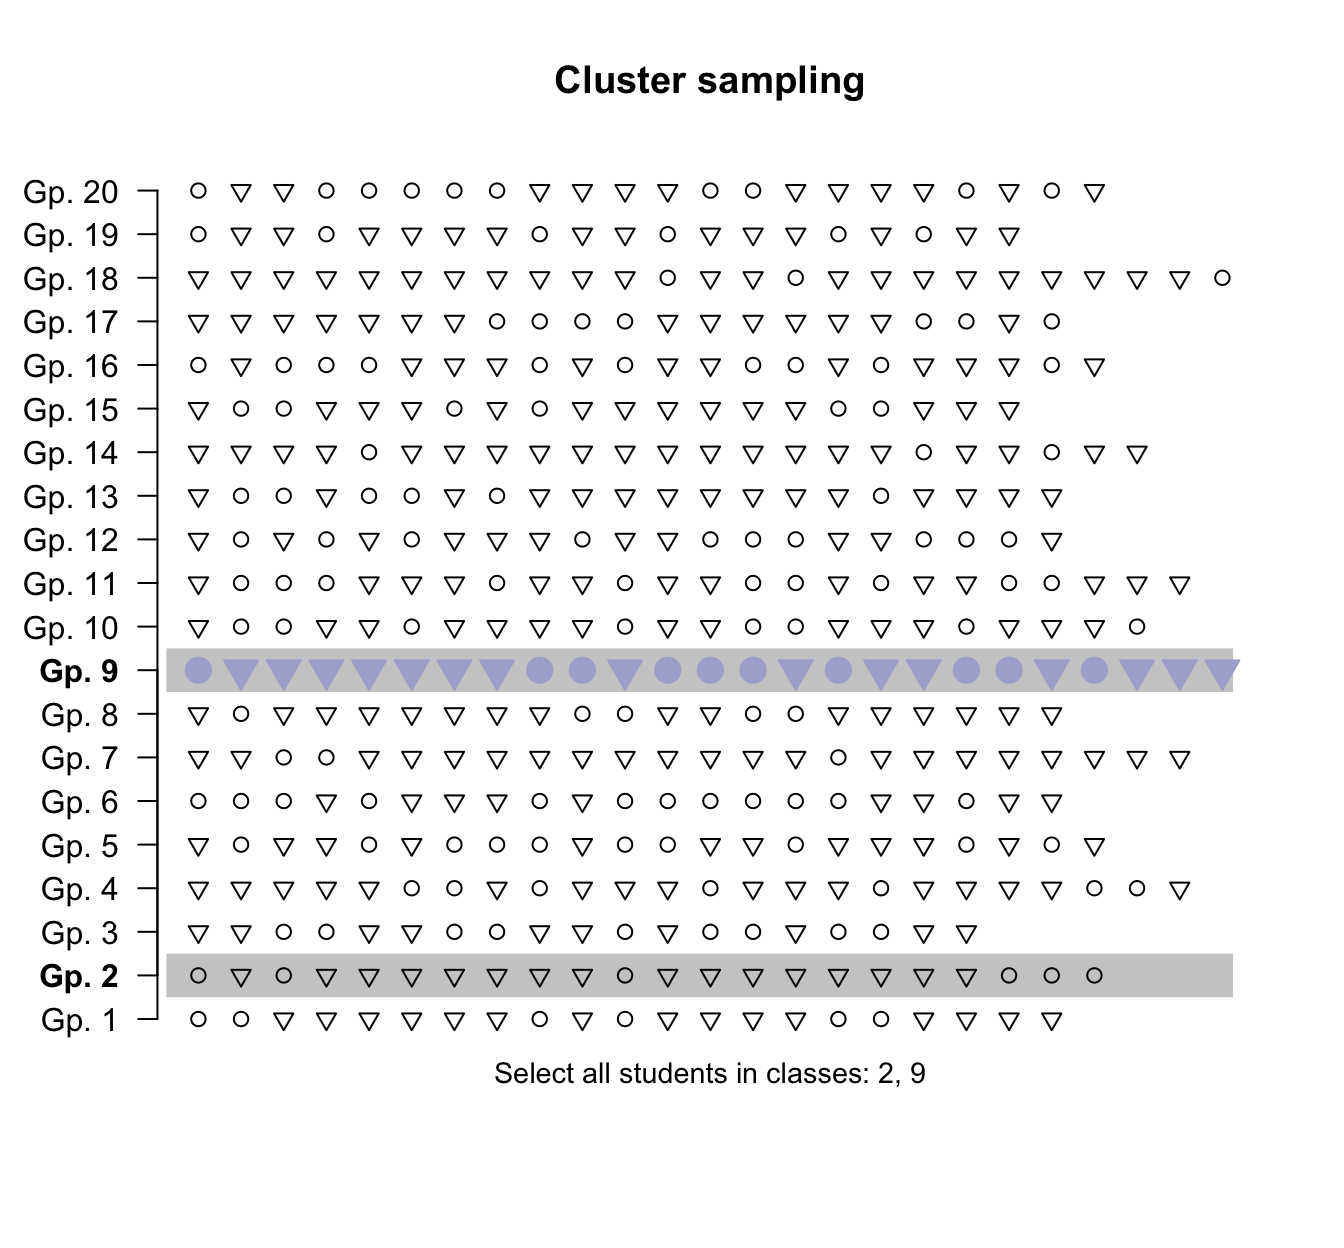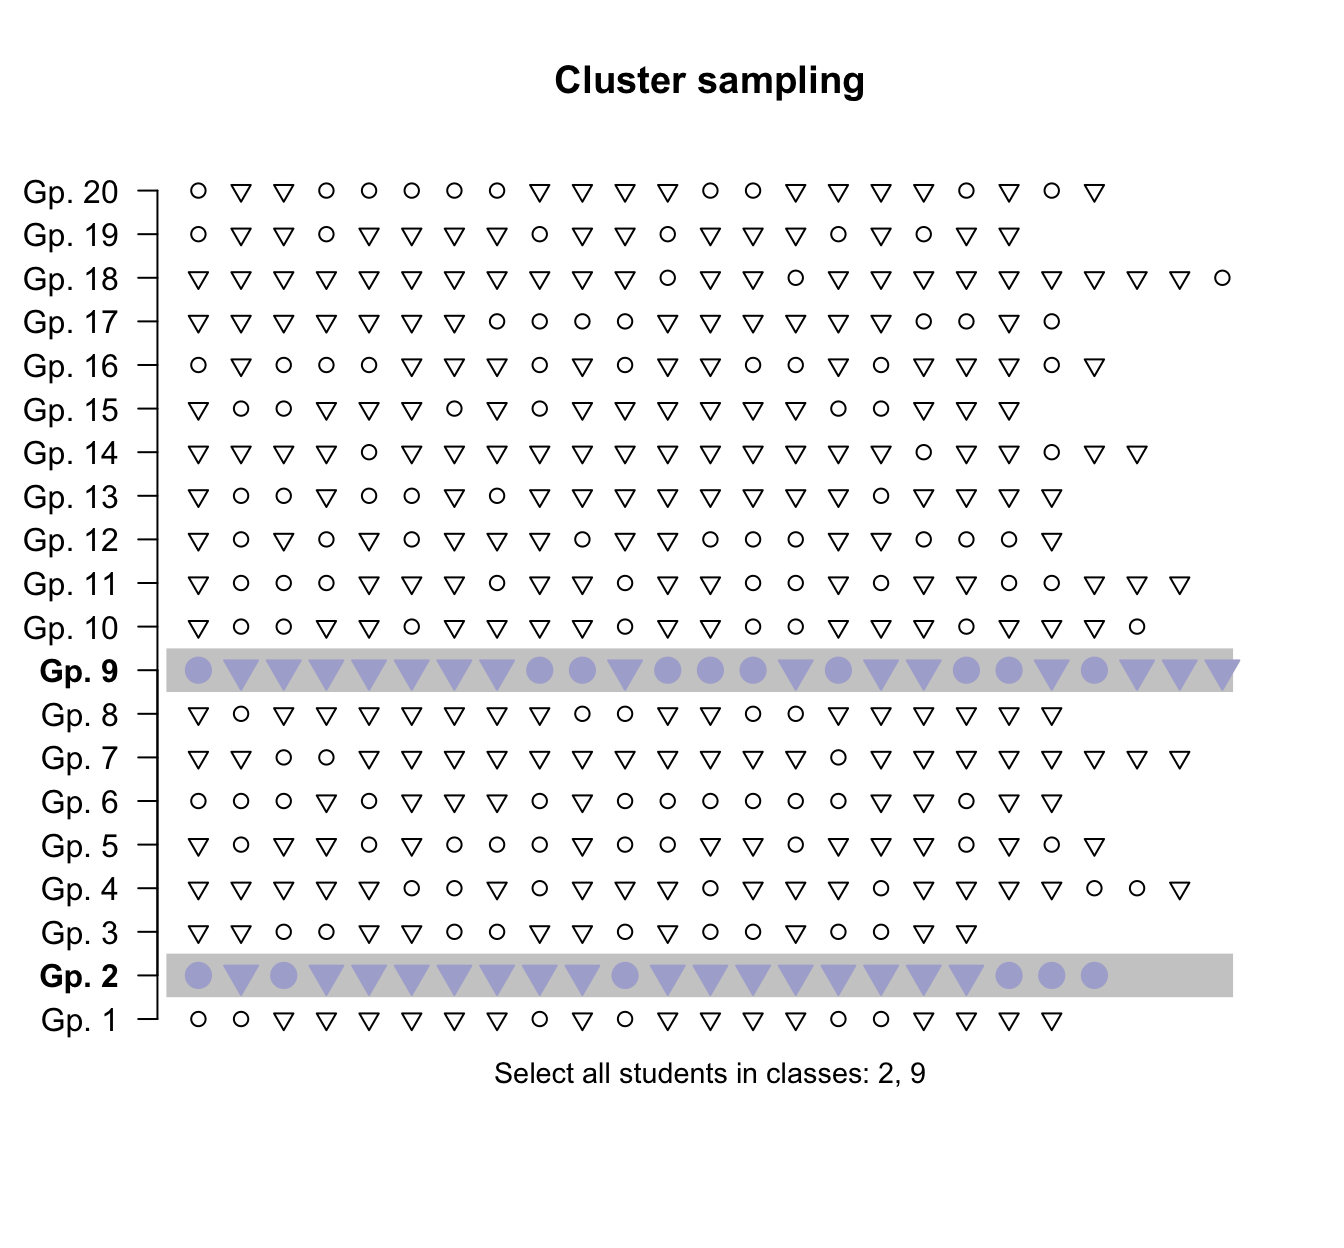
In cluster sampling, the population is split into a large number of small groups called clusters. Then, a simple random sample of clusters is selected, and every member of the chosen clusters become part of the sample. Every individual in the population must be in one, and only one, cluster.
For the study in Example 3.5, a simple random sample of (say) three of the many small-group classes for the course could be selected, and every student enrolled in those selected small groups constitute the sample. By chance, the chosen classes produce a sample size of \(n = 47\) (\(31\) younger; \(16\) older).
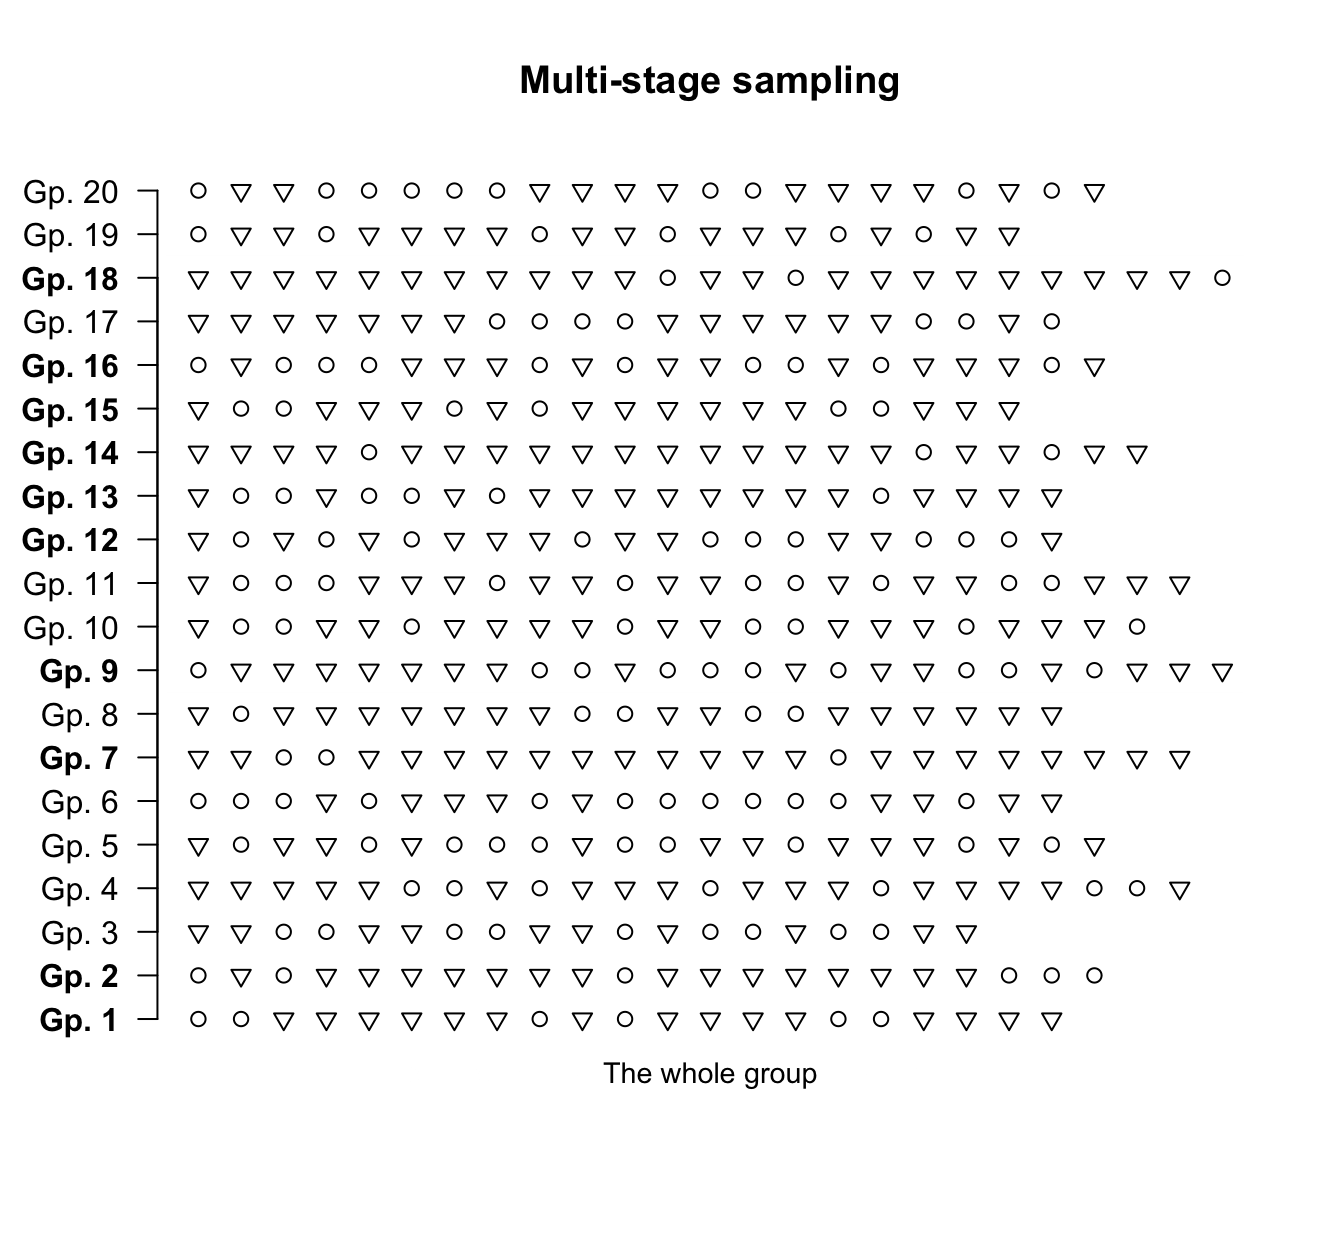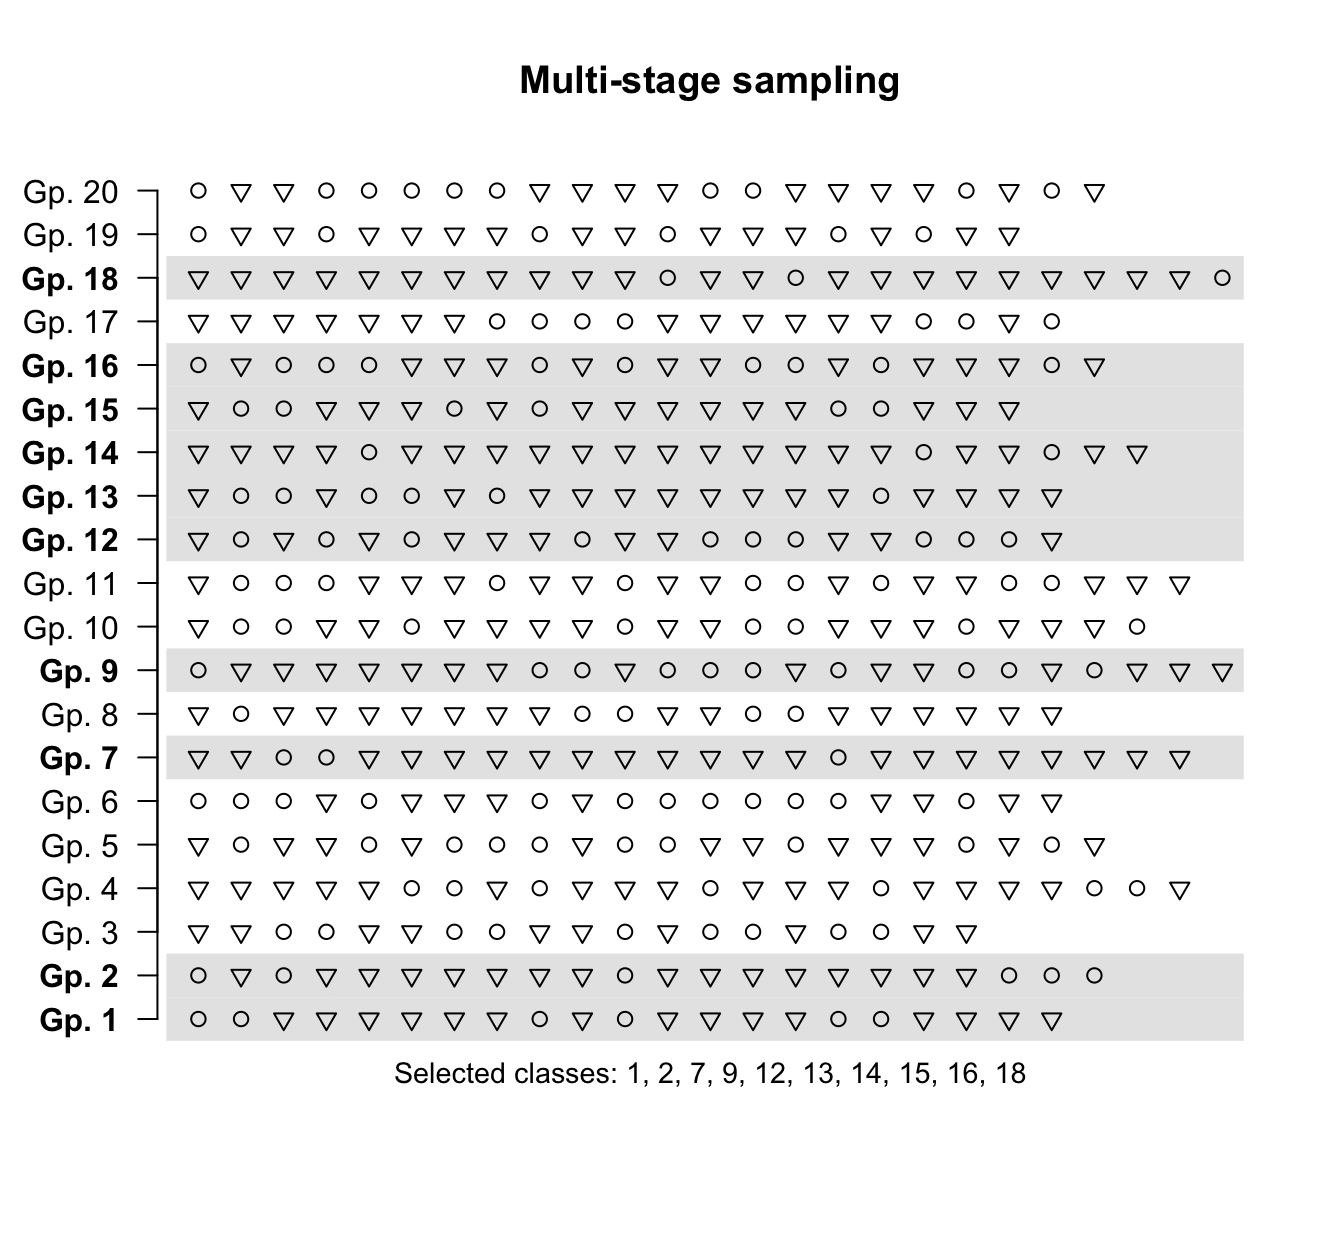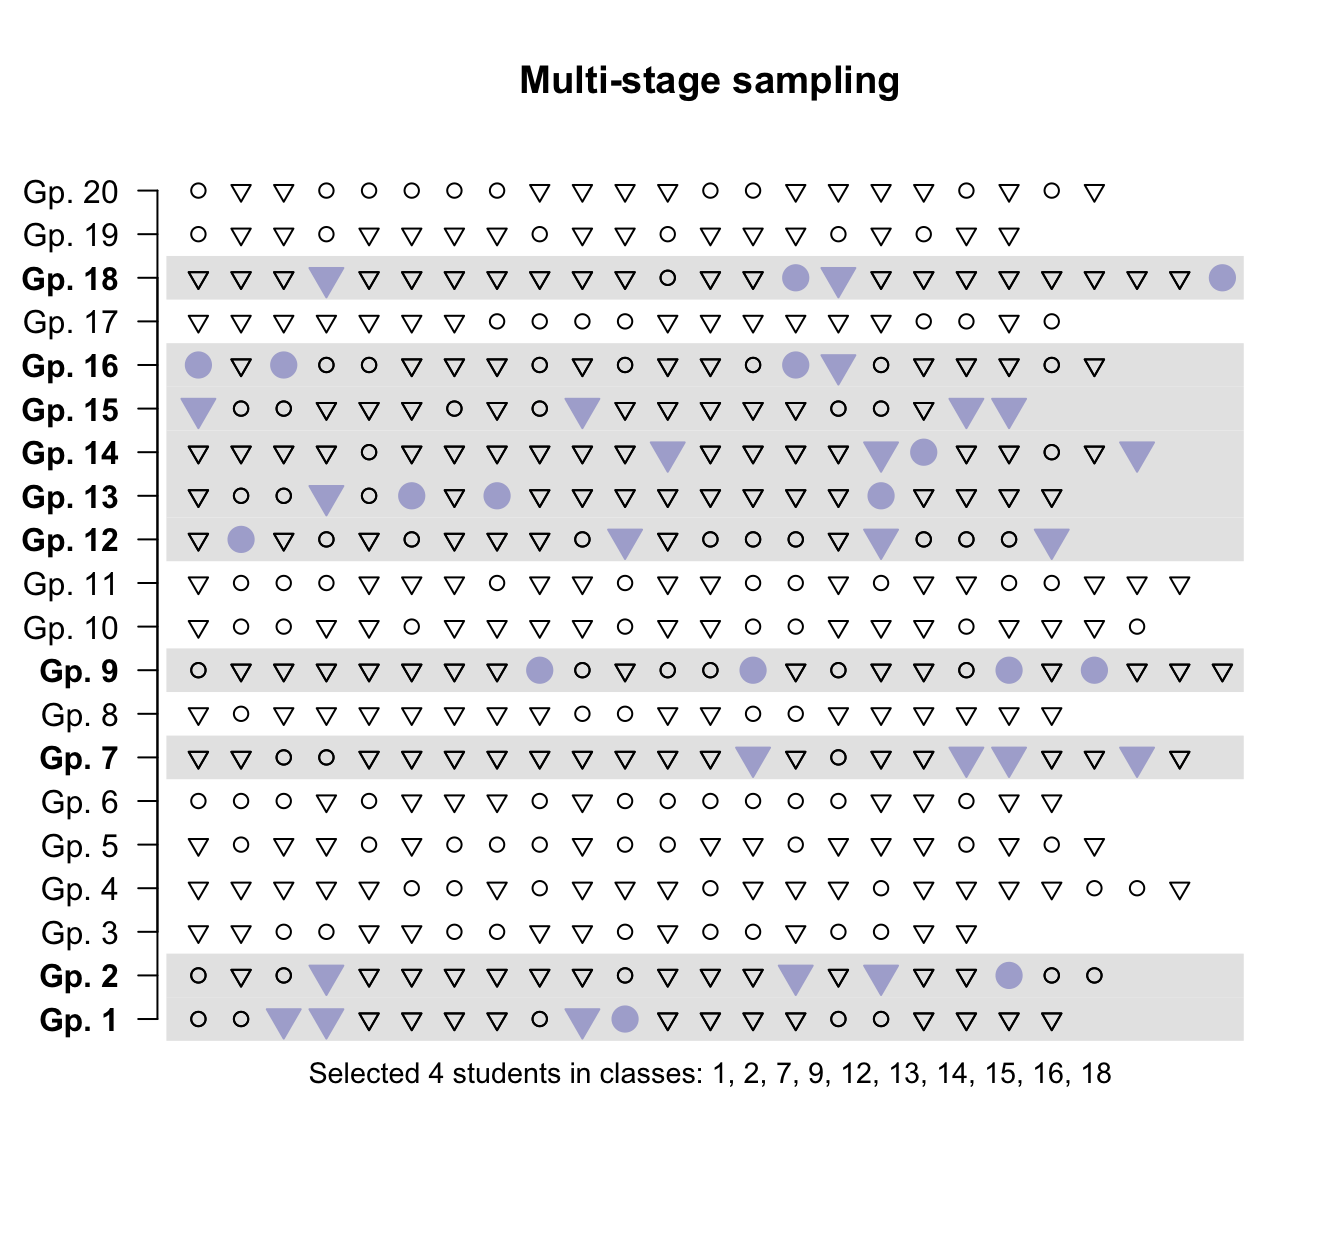
In multi-stage sampling, larger collections of individuals are selected using a simple random sample, then smaller collections of individuals within those large collections are selected using a simple random sample. The simple random sampling continues for as many levels as necessary, until individuals are being selected (at random in each step).
For the study in Example 3.5, a simple random sample of ten of the many small-group classes could be selected (Stage 1), and then four students are randomly selected from each of these \(10\) selected small groups (Stage 2). The sample size is \(10\times 4 = 40\text{,}\) comprising (by chance) \(24\) younger students and \(16\) older students.
The different random sampling methods produce different samples, with different proportions of younger and older students by chance (Table 6.34). Of course, repeating the random sampling processes would produce different samples each time. In all cases, only one of the countless possible samples is studied.
Table6.34.A summary of the various random samples selected using different random sampling methods. In the population, \(66.7\)% of students are younger students. Repeating any random sampling method is likely to produce a different sample each time.
Obtaining a truly random sample is usually hard or impossible in practice. Sometimes the best compromise is to select a sample sufficiently diverse so that it is likely to be somewhat representative of the diversity in the population. Specifically, those in the sample are not likely to be different from those not in the sample, at least for the variables of interest. This is often the only practical way to sample.
In a representative sample, those in the sample are not likely to be different from those not in the sample, at least for the variables of interest. A representative sample is not a random sample.
As always, the results from any non-random sample may not generalise to the intended population (but will generalise to the population which the sample does represent).
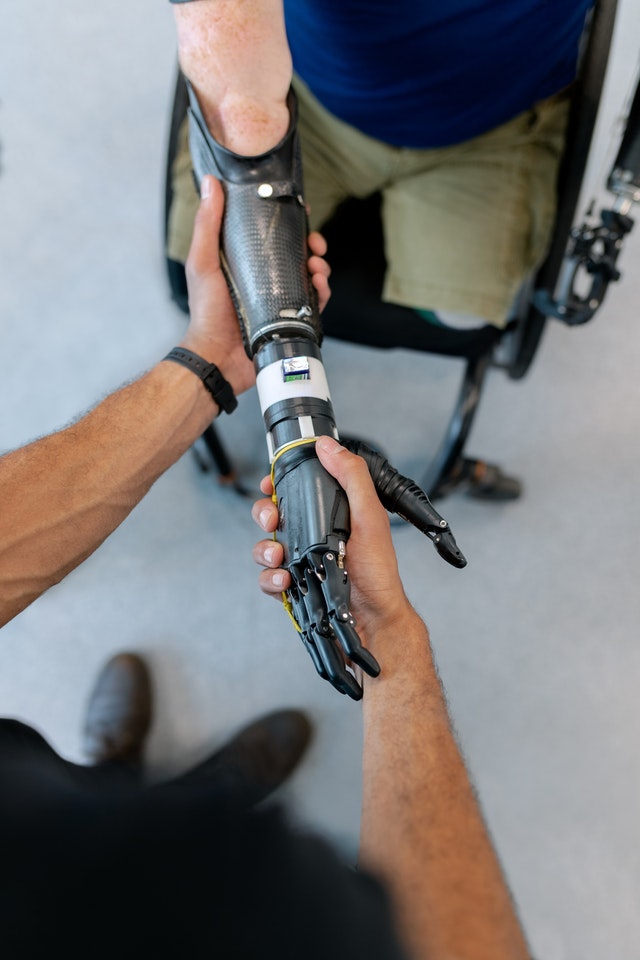
If a randomly-chosen group of Alaska and Texas residents is asked for their feedback, probably (but not certainly) their views would be similar to those of all Americans. No obvious reason exists for why residents of Alaska and Texas would be very different from residents in the rest of the United States, regarding their view of hand prosthetic functionality.
Even though the sample is not a random sample of all Americans, the results may generalise to all Americans (though we cannot be sure). This sample may be representative of the population.
A sample of Texas residents would not be expected to represent all Americans: it would over-represent the average number of hours air-conditioners are used for cooling in summer. In this case, those in the sample are very different to those not in the sample, regarding their air-conditioners usage for cooling in summer.
In contrast, suppose a sample of Alaskans was asked the same question. This sample would not represent all Americans either (it would under-represent air-conditioner use). Again, those in the sample are likely to be very different to those not in the sample, regarding their air-conditioners usage for cooling in summer. This sample would not be representative of the population.
Sometimes, a combination of sampling methods is used. If the combination includes a non-random sampling method, the sampling method does not produce a random sample, but is probably more likely to produce an externally valid sample than a completely non-random sample.
In a study of pathogens present on magazines in doctors’ surgeries in Dublin, some suburbs can be selected at random, and then (within each suburb) all surgeries are contacted, and some surgeries volunteer to be part of the study. This study does not use a random sample.
In 2010, a stratified random sampling procedure was used to select representative cross-sections of providers working in licensed center-based programs and licensed providers of family home-based care from publicly available lists. […] Additional participants were also recruited in 2016 using a combination of stratified random and open, convenience-based sampling.
Sometimes, practicalities dictate how the sample is obtained, which may result in a non-random sample. Even so, the impact of using a non-random sample on the conclusions should be discussed (Chapter 8). Sometimes, simple steps can be taken to obtain a sample that is more likely to be representative.
Random samples are often difficult to obtain, and sometimes representative samples are the best that can be achieved. In a representative sample, those in the sample are not obviously different from those not in the sample. Try to ensure that a broad cross-section of the target population appears in the sample.
Even if a random or representative sample cannot be obtained, the study can still be useful. The results still apply to the population represented by the sample. If individuals in the sample are unlikely to be different from individuals not in the sample, for the variables important to the study, the results are likely to approximately apply to the population.
For the typing study in Example 3.5, only selecting students who attend the gym, or only students who are at a certain café, is unlikely to be somewhat representative of the student population. Instead, the researchers could approach students at different days, times and locations:
This is not a random sample, but should contain a variety of students. Ideally, students would not be included more than once in the sample, though this is often difficult to ensure. The students in the sample are probably somewhat similar to those not in the sample in terms of average typing speeds (there is no obvious reason why they would not be), but we cannot be sure.
To determine if the sample is somewhat representative of the population, sometimes information about the sample and population can be compared. The researchers may then be able to make some comment about whether the sample seems reasonably representative. For example, the sex and age of a sample of university students may be recorded; if the proportion of females in the sample, and the average age of students in the sample, are similar to those of the whole university population, then the sample may be considered somewhat representative of the population (though we cannot be sure).
[38] studied the adoption of electric vehicles (EVs) by Americans, using a sample of \(121\) people found through social media (such as Facebook) and professional engineering channels. This is not a random sample of Americans.
The authors compared some characteristics of the sample with the American population from the \(2010\) census. Compared to the US population, the sample contained a higher percentage of males, a higher percentage of people aged \(18\)–\(44\text{,}\) and a higher percentage of wealthy individuals.
The sample may not be representative of the population for many reasons, all of which compromise how well the sample represents the population (i.e., compromises external validity and accuracy). This is called selection bias.
Selection bias is less common in studies with forward directionality, compared to studies that are non-directional or have backward directionality (Section 4.6). Selection bias may occur if the wrong sampling frame is used, or non-random sampling is used. The sample is biased because those in the sample may be different from those not in the sample (which may not always be obvious). Biased samples are less likely to produce externally valid studies.
Consider Example 6.37, about estimating the average time per day that air conditioners are used for cooling in summer. Even a random sample of Alaskans produces a biased sample of Americans: the sampling frame (Alaskans) does not represent the target population (“Americans”). This is selection bias.
Non-response bias occurs when chosen participants do not respond. Bias occurs because those who do not respond may be different from those who do respond. Non-response bias can occur because of a poorly-designed survey, using voluntary-response sampling, chosen participants refusing to participate, participants forgetting to return completed surveys, etc.
Consider a study to determine the average number of hours of overtime worked by various professions. People who work a large amount of overtime may be too busy to answer the survey. Those who answer the survey may be likely to work less overtime than those who do not answer the survey. This is an (extreme) example of non-response bias.
Response bias occurs when participants provide incorrect or false information. This may be intentional (for example, respondents lie) or non-intentional (for example, the question is poorly written (see Subsection 9.3.1), personal, or misunderstood).
Obtaining data using a telephone survey only includes people who own a telephone, who answer the phone, who do not hang up, who volunteer to complete the survey, and who then finish the whole survey. The people who participate in the survey must meet these criteria, and probably do not represent the population.
Obtaining data using a TV station call-in at \(6\text{:}\)\(15\)pm only includes people watching that channel, at that time, and who are sufficiently motivated to call. These people must meet very specific criteria, and probably do not represent the population.
Randomly sampling students at your university, because it is easier than finding a random sample of all university students in your country, will only generalise to students at that university and not to students at all universities in your country.
Almost always, the entire population of interest cannot be studied, so a sample (a subset of the population) must be studied. Many samples are possible; only one sample is studied. Samples can be obtained using random or non-random methods. Conclusions made from random samples can usually be generalised to the population (that is, they are externally valid and accurate).
Random sampling methods include simple random samples, systematic samples, stratified samples, cluster samples, and multi-stage samples. Random samples are likely to be externally valid and accurate.
Non-random sampling methods include convenience samples, judgement samples, voluntary (self-selecting) samples, and cherry-picking. Random samples are often very difficult to obtain, so reasonably representative samples are sometimes used, where those in the sample are unlikely to be very different from those not in the sample. Non-random samples may not be externally valid or accurate.
Suppose students are randomly selected and sent postal surveys from their university, but some students have moved and so never receive the survey. This is response bias.
For the following scenarios, is the selected sample likely to over- or under-estimate the unknown population value, or estimate the value accurately? Explain why the over- or under-estimation occurs, if relevant, and whether this is likely to be intentional or unintentional.
In a study by biologists to estimate biodiversity, researchers decide to focus only on easily accessible areas of a forest due to budget and time constraints.
A city council wishes to report the crime rate of various neighbourhoods, so employs interviewers to go door-to-door interviewing residents, between \(8\)am and \(5\)pm.
For the following scenarios, is the selected sample likely to over- or under-estimate the unknown population value, or estimate the value accurately? Explain why the over- or under-estimation occurs, if relevant, and whether this is likely to be intentional or unintentional.
A university has introduced a complex and time-consuming system for professors to report students suspected of cheating. When the university produces its Annual Report, the reported incidence of cheating is used to claim that “reports of cheating have dropped”.
A researcher has three months in which to collect the data for a study on car park usage at a shopping centre. Suppose the researcher wants to take a systematic sample of days, and on each of the selected days records the number of cars in the car park.
To select the days in which to collect data, she decides (by using random numbers) to start data collection on a Tuesday, and then every seventh day thereafter.
Suppose you need to estimate the average number of pages in physical books in a university library (with a library in each of five campuses). Describe how to select a sample of \(200\) books using:
Suppose you need a sample of residents from apartments in a large residential complex, comprising \(30\) floors with \(15\) apartments on each floor. You plan to survey the residents of these apartments. For each of the possible sampling schemes given below, first describe the sampling scheme, and then determine which methods are likely to give random (or representative) sample (explaining your answers).
Randomly select five floors, then randomly select four apartments from each of those five floors, and interview a randomly-chosen adult living at the apartment.
Suppose a researcher needs a sample of customers from a large, local shopping centre to complete a questionnaire. Four sampling schemes are listed below. For each, describe the type of sampling. Then, determine which would be the best method (explain why), and determine which (if any) produce a random sample.
The researcher goes to the shopping centre every day for two weeks, at a different time and location each day, and approaches someone every \(15\mins\text{.}\)
[73] investigated how children in Brisbane travel to state schools. Researchers randomly sampled four schools from a list of all Brisbane state schools, and invited every family at each of those four schools to complete a survey.
A study comparing two new malaria vaccines recruited \(200\) Kenyans who had contracted malaria. These recruits were obtained by approaching all patients with a confirmed malaria diagnosis who were admitted to hospitals. Patients could volunteer for the study or not. The study was then conducted to a high standard. Which of the following statements are true?
Suppose a natural forest region is classified into two quite different zones. Zone A is mostly dunes and lightly vegetated, and on the coastal side of a ridge; Zone B is more densely vegetated and on the inland side of the ridge.
A sample of sugar ants (Camponotus app) is taken from Zone A, and another sample of sugar ants from Zone B, to study the average size of the ants. What is the best description of the type of sampling method being used?
All but \(2\)% of the home buyers have at least one computer at home, and \(62\)% have two or more. Of those with a computer, \(99\)% are connected to the internet.
The article later reveals the survey was conducted online (recall the survey was conducted in 2001). The target population is home buyers; however, home buyers with internet access were far more likely to complete the survey than home buyers without internet access.
Researchers are studying the percentage of farms that use a specific management technique. The researchers randomly select \(20\) regions around the country, then randomly select farms within each region, then ask farmers to volunteer to be in the study.
Researchers are comparing the average time that experienced school teachers and first-year school teachers spend in the sun. The researchers select schools by asking school principals to volunteer their schools, then record information for every teacher in those schools.
The study will be externally valid if which of these statements is true? (a) The sample is representative of all households in the world. (b) The sample is representative of all solar technologies. (c) The sample is representative of all households in Santiago. (d) The sample is representative of all households in Chile.
Suppose the researchers mail surveys to all households in Santiago, and people return the survey if they wished to. What is the best description of this sampling method?
Suppose the researchers randomly select five suburbs in Santiago; then ten streets within each suburb; then ten households on each street. What is the best description of this sampling method?